Small language models just became the cost-effective default
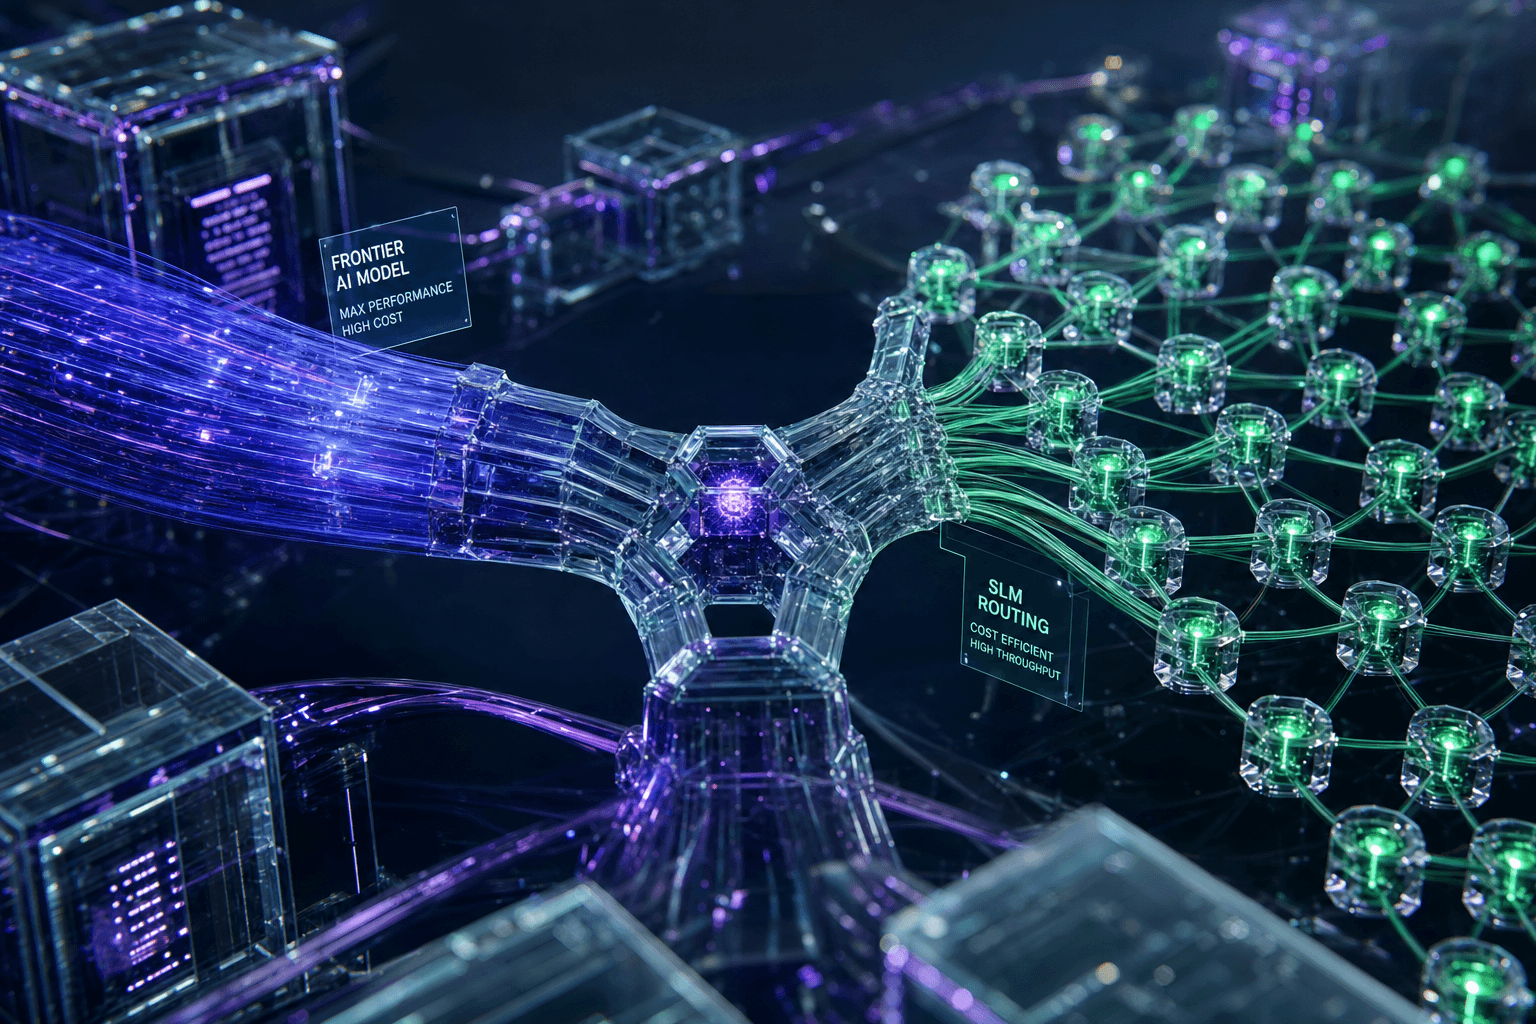
Enterprise AI bills grew 320% while token prices fell 280×. The fix: cost-aware routing cuts spend by 70–90%.
Key Takeaways
- Small language models now match frontier models on specialised tasks at 1/30th the cost per token.
- Enterprises running intelligent workload routing cut AI infrastructure spend by 70-90% with no quality loss.
- Token prices fell 280× but enterprise bills grew 320% because architectures default to expensive models unnecessarily.
- Self-hosting SLMs or using cost-aware routing layers like LiteLLM became operationally routine by 2026.
Enterprise AI bills grew 320% between 2022 and 2026, even as token prices dropped 280×. The culprit isn't usage growth—it's architectural waste. Most organisations still default to expensive frontier models for every task, even when a 3.8-billion-parameter model could handle 90% of workloads at 1/30th the cost.
The FinOps Foundation reported something unexpected in April 2026. After two years of "token it all" culture, 67% of surveyed organizations admitted they were "three months into an uncontrolled AI spend crisis" before implementing any governance.
At the same time, Microsoft Phi-4—a 14-billion-parameter model—outperformed GPT-4o on mathematics reasoning benchmarks. It's 47× smaller than frontier alternatives.
This collision of cost crisis and capability maturity changed the conversation. CTOs across enterprise and mid-market companies began systematically decomposing their AI workloads. They discovered that 60–70% of their tasks could run on small language models (SLMs) at 1/30th the cost per token.
The frontier-first architecture just became obsolete
In 2024, the question was "which frontier model should we use?" By 2026, it became "which models should we use, and how do we route workloads intelligently?"
Three forces converged to make this shift structural, not optional:
Model quality convergence: SLMs crossed the production-quality threshold. Phi-4 achieves GPT-4-level math reasoning on a model small enough to run on a MacBook Pro. Domain-specific fine-tuning on SLMs now outperforms generic frontier models on specialized tasks.
Token economics inverted: Token prices fell from $0.30 to $0.001 per 1M tokens—a 280× reduction. But enterprise token consumption grew 13× over the same period. Agentic workflows, retrieval-augmented generation, and multi-turn conversations resend full context on every API call. Bills skyrocketed despite lower per-token prices.
Deployment infrastructure matured: Self-hosting SLMs was an exotic engineering problem in 2023. By 2026, production-grade serving infrastructure (vLLM, TensorRT-LLM, Text Generation Inference) and cost-aware routing layers (LiteLLM, OpenRouter, Portkey) made hybrid architectures operationally routine.
Understanding the model selection hierarchy
Before you can implement cost-aware routing, you need to understand the architecture decision tree.
Default consideration order:
- SLMs on edge or on-prem GPU: For latency-critical, high-volume tasks (customer service chatbots, content tagging, code review). Cost: ~$0.0001 per 1M tokens (self-hosted). Quality: Production-grade for well-scoped tasks.
- SLMs via inference-as-a-service (vLLM, Together AI): Same use cases, outsourced infrastructure management. Cost: ~$0.05 per 1M tokens. Quality: Identical to self-hosted; ops simplified.
- Frontier models on multi-turn caching infrastructure: For reasoning-heavy or novel tasks. Cost: ~$0.001–$0.01 per 1M tokens (after caching discount). Quality: Top-tier reasoning, but caching overhead requires architectural thought.
- Frontier models with batch API: For overnight batch processing, non-real-time workflows. Cost: ~$0.0005–$0.005 per 1M tokens (50% discount). Quality: Same as standard API.
The routing decision compounds at scale. A typical enterprise running 500M tokens/day defaults to frontier models pays $500/day ($180K/year). Same workload intelligently routed between SLMs and frontier models costs $30–$80/day ($11–$29K/year). That's an 80–85% reduction with no quality degradation if routing logic is sound.
Three technical factors that determine your savings potential
Input vs. output token costs: Output tokens cost 3–5× more than input tokens. In multi-turn conversations, input tokens dominate because full context is resent on each call. A single retrieval-augmented generation call can cost 2–3× more than a simple Q&A because the context window is enlarged. Caching and prompt optimization become business levers.
Token consumption variance: The same task can vary by 10–30× in token cost depending on how the prompt is structured, how much context is retrieved, and whether caching is enabled. This variance is a business lever, not a bug.
Model quality trade-offs are quantifiable: Phi-4 vs. Claude Sonnet for code review might show a 98.5% correlation in output quality but a 32× cost difference. The 1.5% quality gap can often be absorbed by human review loops for high-risk decisions.
Where cost-aware routing delivers maximum ROI
This architecture shift isn't universal. Cost-aware routing is most valuable for:
High-volume, repetitive workloads: Customer service, content moderation, code review, data tagging. 60–80% of these tasks fit SLM capabilities.
Hybrid reasoning tasks: Novel problems requiring frontier models, but routine follow-ups that don't. Example: initial customer inquiry → frontier model reasoning, then SLM-powered follow-up responses.
Organizations with sophisticated DevOps/MLOps capability: Building cost-aware routing requires instrumentation, monitoring, and fallback logic. It's not a one-time setup; it's an ongoing operational discipline.
This does NOT apply to:
- Simple, chat-based internal tools where usage is low-volume and budget-insensitive
- Novel, reasoning-intensive one-offs where capability is genuinely uncertain
- Regulatory or compliance-critical systems where model audit trails must be pristine
4-week cost-aware routing
Phase 1: Audit & Categorize (Week 1–2)
Map all current AI spend. Extract invoice data by model, by application. Tag usage: real-time vs. batch, high-touch vs. repetitive, reasoning-required vs. structured-extraction.
Categorize workloads into three buckets:
- (A) repetitive/high-volume
- (B) hybrid
- (C) novel/reasoning-intensive
Baseline performance/quality for each bucket. For (A) workloads, run a sample against a production SLM (Phi-4 or Gemma 3) and measure output correlation with current frontier model outputs.
Phase 2: Implement Cost-Aware Routing (Week 3–6)
Pick your approach based on team capability:
Option A (Low-lift): Adopt a model router (LiteLLM or OpenRouter). Add a simple config layer: "For task X, route to Phi-4 by default; if Phi-4 fails or returns low-confidence output, escalate to Claude Sonnet." No code rewrites required.
Option B (Medium-lift): Build a lightweight routing layer in your LangChain or n8n automation. Use conditional logic: "If this is a customer service response (high-volume), use Phi-4. If this is a policy interpretation (reasoning-intensive), use Claude."
Option C (High-lift but highest ROI): Self-host Phi-4 or Llama 3.3 on your infrastructure (or rent spot instances for inference). Set up vLLM as a reverse proxy. Route all high-volume traffic here; frontier APIs handle exceptions and edge cases.
Phase 3: Monitor & Optimize (Ongoing)
Set up cost attribution: track spend by application, by task type, by model used. Use FOCUS (FinOps Open Cost and Usage Specification) schema if working with multiple providers.
Create governance: enforce model selection policies. If an application violates the policy (e.g., routes all queries to Claude when 70% could use Phi-4), surface alerts.
Quarterly review: benchmark new SLM releases (they ship every 3–4 months). Re-evaluate whether your routing decisions still hold.
Concrete workflow example
Here's how a customer service workflow changes with cost-aware routing:
[Customer Service Query]
  ↓
[Classify intent (SLM via Ollama on-prem):
 simple FAQ vs. policy question vs. novel issue]
  ↓
- If simple FAQ (70% of queries)
  → Phi-4 (on-prem) → ~$0.0001 cost
- If policy question (20% of queries)
  → Claude Sonnet with batch caching
  (~$0.001 cost, 4-hour delay acceptable)
- If novel issue (10% of queries)
  → Claude Sonnet real-time (~$0.01 cost)
  ↓
[Log cost by category, escalate if cost exceeds threshold]
Integration points:
n8n automations: Add a routing node that checks task type, queries LiteLLM API, and selects model based on cost/quality parameters.
APIs: Wrap OpenAI/Claude SDK calls with a cost-aware middleware layer (use @portkey-ai/gateway or LiteLLM's Python client).
CRM systems: Log AI model selection and cost per customer interaction; use this to justify premium service tiers or internal ROI calculations.
This compounds with scale
The enterprise AI infrastructure transition happening right now parallels the cloud database evolution of 2010–2015. Companies defaulted to massive data warehouses (expensive, slow, centralized). Over time, architectures evolved to use the right tool for the job: SQL for transactional work, NoSQL for scale, data lakes for analytics.
Today, the same disaggregation is happening in AI. Organizations that systematically apply cost-aware routing will operate with 2–3× better unit economics than competitors who assume all tasks require the frontier model.
If your opponent is paying $180K/year for AI infrastructure and you're paying $20K for identical output, you have structural margin. In a recession, that's survival. In growth mode, that's margin advantage you can reinvest in features or pricing flexibility.
Get the Enterprise AI Cost Audit Playbook: A 1-hour workshop template (with n8n workflow examples) that helps CTOs categorize their AI workloads and estimate 90-day savings using SLM routing. Includes a cost calculator showing the 70–90% reduction potential.
Book an AI Infrastructure Optimization Engagement: 4-week assessment covering spend audit, workload categorization, SLM baseline testing, cost-aware routing design, and ROI projection. Position this as a prerequisite before scaling AI spend further.
Want more on
Enterprise Architecture?
Add this topic to your Custom Digest. Drop your email to get our deepest insights on this exact topic.
Ready to fast-track your business?
We combine enterprise-level technical strategy with your existing business to solve complex blockers and accelerate your growth. Let's build something remarkable.
Partner With UsUp Next
Continue your journey into Enterprise Architecture.
AI governance must move from finance to operations
AI spending is out of control because governance runs through finance instead of operations, where token costs happen in real time.
How content data models empower marketing SEO velocity
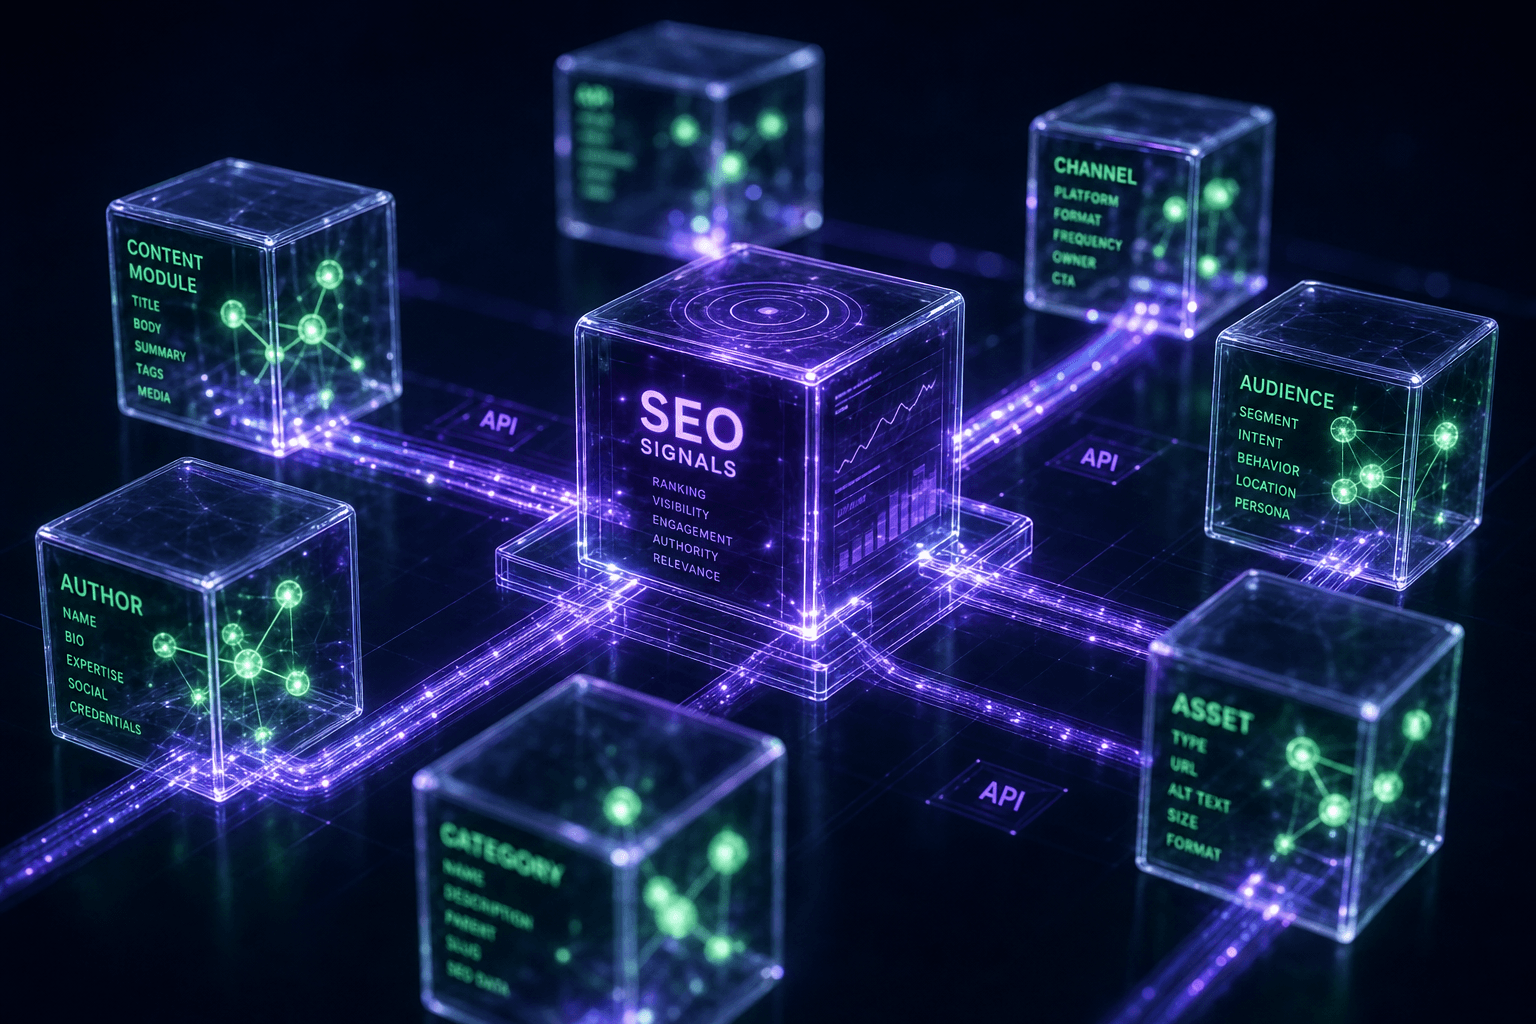
Learn how structured content data models let marketing teams ship SEO-optimised content faster without waiting on engineering resources.
Structuring 10x cost-per-answer benchmark nobody is measuring
When you measure cost per correct answer instead of cost per token, fine-tuned 7B models beat frontier APIs by 5-10x on narrow, high-frequency tasks.