Why keeping full agent histories beat every compression strategy
Full context retention with prefix caching cuts agent token costs by 90% and outperforms every summarization strategy on recall.
Key Takeaways
- DeepSeek's 90% cache discount and Anthropic's 10× multiplier make full-context retention cheaper than summarisation.
- Production agents transmit 100 input tokens for every output token, making prefill cost the dominant expense.
- Capping tool outputs at fixed sizes preserves cache hits while preventing bloat across multi-turn agent loops.
- Cache architecture is now a core infrastructure concern that directly impacts agent deployment profitability at scale.
A single architectural change reduced browser-agent token costs by 90% in October 2026: switching from summarisation to cache-first loop design. DeepSeek's prefix caching offers a 90% discount on cached tokens versus fresh tokens, and research from Towards AI shows that keeping full conversation history with prefix caching beats every summarisation strategy on both cost and memory recall.
RTRVR reported in October 2026 that a single architectural shift reduced their browser-agent token costs by 90%. The move: switching from summarization to cache-first loop design. DeepSeek's prefix caching offers a 90% discount on cached tokens versus fresh tokens. A similar finding from Towards AI (August 2026) showed that keeping full conversation history with prefix caching beat every summarization strategy on both cost and memory recall.
For years, engineers treated agent context as a management problem—summarize, compress, trim. But research from mid-2026 reveals the opposite: full-context retention plus prefix caching beats every summarization strategy on cost, latency, and recall at the same time.
The agent loop's economics problem
Agent deployments face an acute cost issue: a single tool call in an agent loop re-sends the entire system prompt (2,000–6,000 tokens), tool schemas (1,000–4,000 tokens), conversation history (500–2,000 tokens), and tool outputs (500–3,000 tokens). Over 50 tool calls to complete a task, you're transmitting 100+ tokens of fixed overhead for every new step.
Typical production agents generate ~100 input tokens for every output token (Manus Research, July 2025). A task requiring 50 tool calls transmits 100,000+ input tokens to generate 5,000 output tokens. Cost is dominated by prefill, not generation.
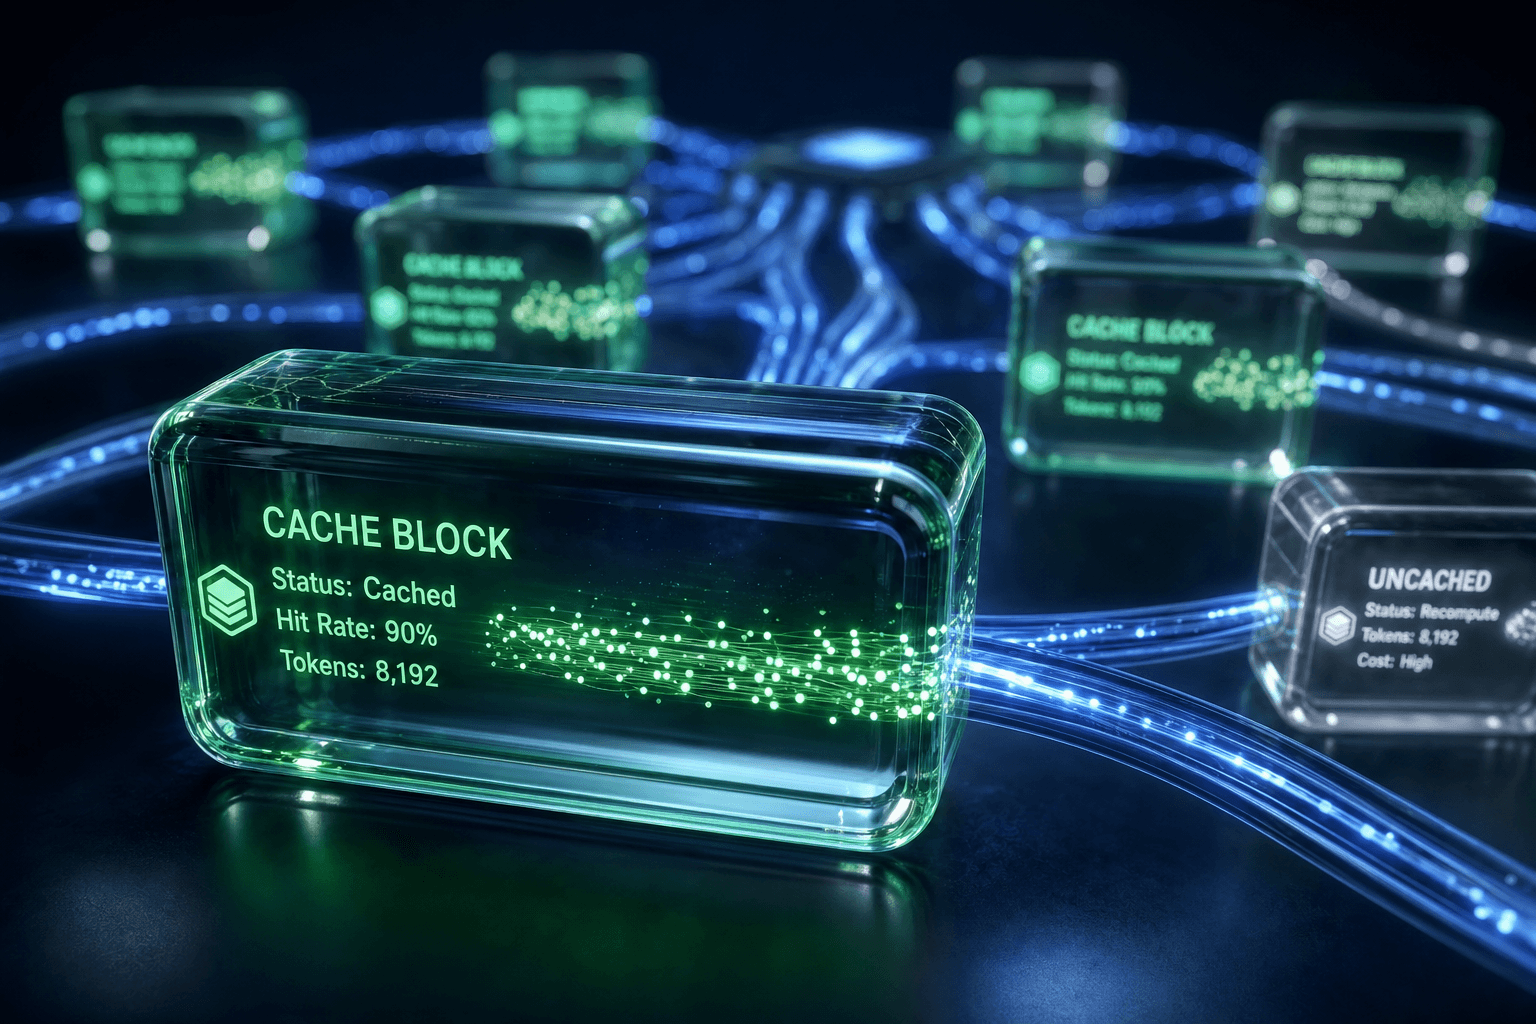
Prefix caching changes this: if the first 5,000 tokens (system prompt, tools, history up to turn 5) are identical across requests, the platform caches them and bills at a 90% discount. The cache breaks if the first new token differs, forcing full-price recomputation.
Why bigger context windows didn't solve this
"Lost in the Middle" (Liu et al., 2023) and "NoLiMa" (Modarressi et al., 2025) showed that frontier models degrade as context length grows. A 200,000-token window showed accuracy cliffs by 50,000 tokens. Placing relevant facts in positions 5–15 of a 20-document context cost 30+ accuracy points compared to front or back placement.
Bigger windows don't solve context management—they amplify noise.
Why compression failed
Summarization rewrites the prefix, invalidating cache hits and forcing full-price recomputation. A summary breaks cacheable byte-identity. You lose recall of exact tokens, forcing re-fetches of discarded details.
The prefix caching economics
Provider Cached Token Price Uncached Price Discount Anthropic Claude Sonnet $0.30/M $3.00/M 10× DeepSeek Context Caching $0.014/M $0.14/M 90% off
Transformers pre-compute KV cache (key-value tensors) for every token of the prompt. If your next request's prefix is byte-identical up to token N, the serving stack reuses that cache and skips recomputation. First token differs? Cache invalidated from that point onward.
The 2026 insight: Full history wins
Towards AI measurement (August 2026) found that keeping full history beat every summarization strategy:
- Full history + caching: $0.14/request + 90% discount on cache hits = $0.014/cache-hit
- Summarized + fresh: $0.14/request (no cache benefit from prefix rewrite)
- Trimmed history: $0.07/request + partial cache benefit (but lost memory of trimmed facts)
Name your constraint first
The decision rule depends on your bottleneck:
- Cached input price above ~$0.55/M? → Cap tool outputs at fixed sizes (500 tokens max) to avoid cache invalidation. Output size doesn't change cache hits.
- Window doesn't fit? → Compress. But compress early (before caching), not mid-loop.
- Recall accuracy is critical? → Full history + semantic filtering. Cache the full conversation; use embeddings to retrieve relevant facts at tool-call time.
When this applies (and when IT doesn't)
Use cache-first architecture for:
- Long-running agent tasks: Coding agents, research assistants, multi-turn conversations (5+ turns)
- Cost-sensitive deployments: Browser agents, autonomous workflow systems, high-throughput automation
- Evaluating new models: Check their cache pricing before choosing; a model with cheap caching can outperform a "smarter" model with expensive tokens
Skip caching for:
- Single-turn request/response (no prior context to cache)
- Highly variable system prompts or tool schemas (invalidates cache on every request)
- Low-volume deployments where token cost is negligible
How to implement cache-first agent loops
Step 1: Profile your current agent
Run 50 task completions through your agent. Record:
- Average tokens per request (input + output)
- Average number of tool calls per task
- Conversation history size at task completion
- Cost per completed task
Step 2: Choose your cache target
Option A: DeepSeek cache-first loop (highest savings)
Use DeepSeek API with native prefix caching enabled. System prompt and tool definitions are cached (not recomputed). Conversation history appends after cached prefix. New tool outputs do NOT rewrite the prefix (append-only).
Example request structure:
{
  "model": "deepseek-chat",
  "messages": [
    {"role": "system", "content": "You are a coding assistant..."},
    {"role": "user", "content": "Function definitions (cached in prefix)"},
    {"role": "assistant", "content": "Tool call 1 result"},
    {"role": "user", "content": "New query (appended, cache hit expected)"}
  ],
  "cache_control": {"type": "ephemeral"}
}
Option B: Anthropic cache-first with Claude
Set cache_control on system prompt and tools. Use append-only conversation history (no rewriting prior turns). Monitor cache hit rate via response headers.
Option C: n8n + OpenAI (simplified)
Use OpenAI's prompt caching (cheaper than raw uncached). Store conversation in Pinecone or Chroma for semantic retrieval. Only pass top-K relevant messages plus system prompt to each request.
Step 3: Implement output capping
Most agent cost gains come from capping tool outputs, not shortening history:
def run_agent_with_capped_output(query):
    response = agent.execute(query)
    # Cap output before it goes back into next request
    capped_output = response[:500]  # Max 500 tokens per tool output
    return capped_output
This preserves cache hits while preventing bloat.
Step 4: Monitor cache effectiveness
Track over 2-week baseline:
- Cache hit ratio (requests hitting cache / total requests)
- Cost per completed task
- Task latency (cached requests are faster; P50 should drop 10–20%)
- Accuracy metrics (full context should maintain or improve recall)
Expected improvements: 60–80% cache hit rate, 40–70% cost reduction, 10–20% latency improvement.
Step 5: Iterate on context strategy
Once caching is active:
- Identify which tool outputs are bloated; cap the largest ones first
- Add semantic filtering at tool-result time (use embeddings to rank which tool results matter most)
- For very long histories (50+ turns), add a lightweight summarization gate that runs offline (doesn't break the cache)
Cache architecture is now a business concern
In 2024–2025, the agent narrative was "smarter prompts, better models, more tools." In late 2026, it's "understand your cache."
The best engineers aren't fine-tuning models or writing elaborate prompts—they're building systems where the most-used facts (system prompt, common tool definitions, early conversation history) are cached and reused across hundreds of requests.
This is unsexy infrastructure work, but it's where 90% cost reductions actually come from. If you're running agents at any scale, cache strategy is now a business concern, not a nice-to-have. The teams that nail this will ship faster, scale cheaper, and hit profitability before those still compressing context manually.
Understanding which system prompts, tool schemas, and conversation histories should be cached—and how to avoid invalidating the cache with every new message—is now a core infrastructure concern that directly moves the business needle.
Ready to cut your agent costs by 60–80%? WrightyMedia's "Agent Cost Audit & Cache Strategy Design" is a 2-week engagement to profile your current agent deployment (cost per task, token breakdowns), evaluate cache strategies for your specific provider and model, and deliver a cache-optimized architecture with expected cost reduction and implementation timeline. Deliverable: audit report, cache strategy blueprint, and reference implementation code.
Get the Agent Token Cost Calculator — A free interactive tool: input your task type (coding agent, research assistant, browser automation), model choice, and current token costs; get a projected cost reduction with cache implementation and a prioritized optimization roadmap.
Want more on
Enterprise Architecture?
Add this topic to your Custom Digest. Drop your email to get our deepest insights on this exact topic.
Ready to fast-track your business?
We combine enterprise-level technical strategy with your existing business to solve complex blockers and accelerate your growth. Let's build something remarkable.
Partner With UsUp Next
Continue your journey into Enterprise Architecture.
Orchestrating agents across governed processes, not building smarter agents
How to coordinate multiple AI agents across regulated workflows without losing audit trails, control, or budget.
Building for composable commerce
Learn how decoupling your frontend from backend systems cuts IT debt, speeds releases, and breaks vendor lock-in.
Empowering marketing teams
How API-first frontends let marketing teams launch campaigns without engineering tickets, cutting time-to-market by half.