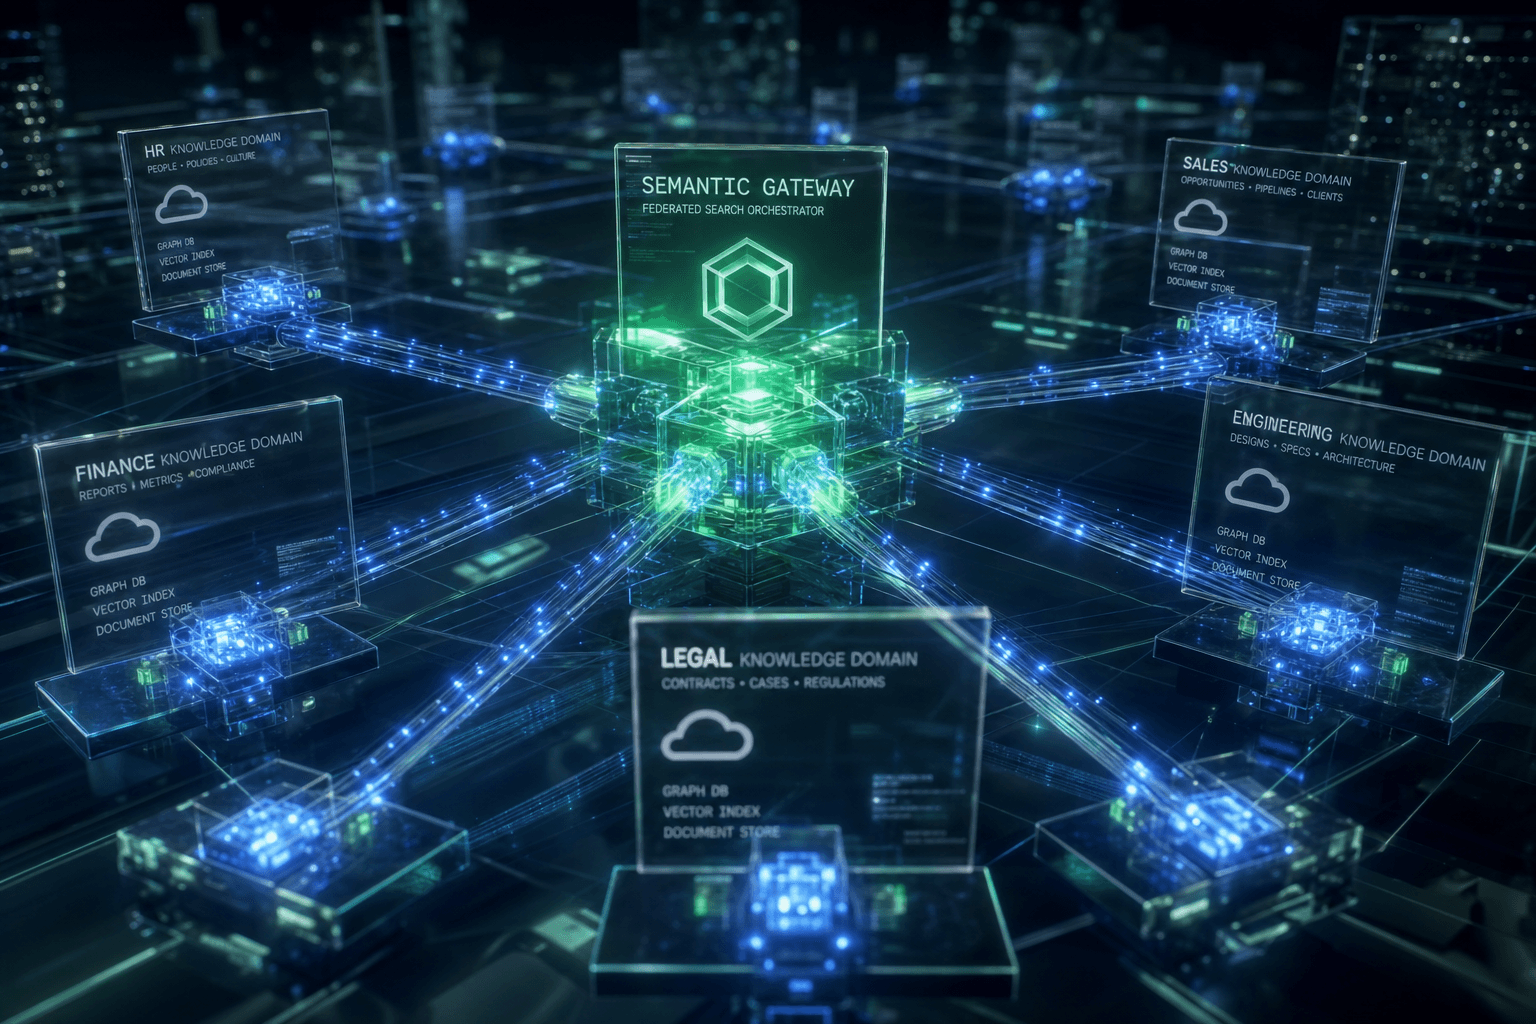
Federated knowledge planes as modern enterprise search layers
CTOs can unify fragmented enterprise data through federated knowledge planes, cutting search time and reducing IT debt.
Key Takeaways
- Fragmented enterprise data slows decision-making and traps knowledge workers in endless manual searches.
- Federated knowledge planes unify disparate systems without creating another data silo or vendor lock-in.
- Semantic layers and vector search enable AI to pull accurate context from your existing infrastructure.
- Faster information retrieval directly improves productivity, customer response times, and revenue velocity.
Enterprise search is broken. Your teams waste hours hunting for information trapped across disconnected systems, dragging down productivity and decision speed. Federated knowledge planes fix this by creating a unified view of your data without migrating it into yet another centralised platform.
Your CTO receives a Slack message at 9:47 AM: "Do we have the updated pricing model for the enterprise tier?" Simple question. The answer exists somewhere in your organization—buried in a Confluence page, attached to a closed Salesforce opportunity, or nested three folders deep in SharePoint.
Twenty minutes and four system logins later, your team still doesn't have the answer.
This isn't a training problem. It's an architectural failure.
The real cost of fragmented knowledge
Enterprise knowledge fragmentation creates measurable damage:
- Sales engineers spend 19% of their week searching for technical documentation
- Product teams duplicate research that already exists in another department's drive
- Customer success can't access the engineering context behind feature releases
- New AI initiatives fail because LLMs can't reach the institutional knowledge they need
Traditional enterprise search throws technology at a structural problem. You index everything, add a search bar, and hope semantic matching works. It doesn't. Context gets stripped. Permissions break. Results lack relevance because the search engine doesn't understand how your CRM data relates to your product specs.
The real issue: your knowledge architecture treats data sources as independent kingdoms instead of federated territories.
What federated knowledge planes actually are
A federated knowledge plane is an abstraction layer that creates a unified logical view of disparate data sources without physically moving data into a central repository.
Think of it as a translation and routing layer. When someone searches for "Q4 pricing model," the federated plane:
- Translates the query into a semantic request
- Identifies which systems likely contain relevant information
- Queries those systems through secure APIs
- Synthesizes results with preserved context and permissions
- Returns a unified answer that maintains data sovereignty
This differs fundamentally from data lakes or warehouses. You're not ETL-ing everything into Snowflake and hoping for the best. You're building an intelligent routing fabric that knows where information lives and how to retrieve it without creating yet another data silo.
The architecture that makes this work
Semantic data layer
Start with a canonical data model that describes your organization's knowledge taxonomy. This isn't a database schema—it's an ontology that defines:
- Entity types (customers, products, contracts, engineering decisions)
- Relationships between entities (which customer uses which product)
- Metadata standards (how dates, currencies, and statuses are represented)
- Semantic tags that create context across systems
Use open standards like JSON-LD or Schema.org vocabularies. Avoid proprietary formats that lock you into vendor ecosystems.
Your semantic layer maps how a "customer" in Salesforce relates to a "user" in your product database and an "account" in your billing system. Without this mapping, federated search returns disconnected fragments.
Federated data access gateway
Build an API gateway that provides uniform access to underlying systems. This gateway handles:
Authentication and authorization: Single sign-on that propagates permissions from source systems. If a user can't access a Confluence space, the gateway shouldn't return those results.
Data transformation: Converting REST responses, GraphQL queries, and database results into your canonical data model.
Query routing: Intelligent distribution of search requests to relevant systems based on query semantics.
Caching and optimization: Storing frequently accessed metadata to reduce API load on source systems.
The gateway maintains data sovereignty. Information stays in its original system. You're not creating compliance nightmares by replicating sensitive data.
Vector search and rag integration
Deploy an open-source vector database (Qdrant or Milvus) to index your semantic layer. This enables:
Embedding generation: Convert documents, database records, and structured data into vector representations that capture semantic meaning.
Similarity search: Find conceptually related information even when keyword matches fail.
RAG pipeline orchestration: When a user asks a question, your system:
- Generates an embedding for the query
- Performs vector similarity search to identify relevant chunks
- Uses the federated gateway to retrieve full context from source systems
- Feeds retrieved context to a self-hosted LLM
- Synthesizes an answer that cites sources and maintains permissions
This architecture lets you run GPT-4 or Llama against your proprietary data without sending everything to OpenAI. Your LLM becomes a reasoning engine over a knowledge plane that respects security boundaries.
Implementation blueprint
Phase 1: Semantic foundation (weeks 1-4)
Define your canonical data model. Start with your five most critical entity types. Map how they appear across your top three systems (probably CRM, product database, and document management).
Build transformation logic that normalizes these entities into your standard format. Write tests that validate relationship integrity.
Phase 2: Gateway construction (weeks 5-8)
Implement your federated access layer. Begin with read-only access to reduce risk. Build adapters for each source system's API.
Focus on permission propagation. Your gateway must enforce the same access controls as source systems or you've created a security vulnerability.
Phase 3: Search infrastructure (weeks 9-12)
Stand up your vector database. Generate embeddings for existing content using an open model (sentence-transformers or a hosted embedding API).
Build your RAG pipeline. Start with simple retrieval, then add LLM synthesis. Use a small, fast model (Llama 3 8B) for prototyping before graduating to larger models.
Phase 4: Refinement and expansion (weeks 13+)
Monitor query patterns. Identify which searches return poor results and refine your semantic mappings.
Expand to additional data sources incrementally. Each new system requires adapter development and semantic mapping, but your core architecture doesn't change.
The outcomes that matter
This architecture delivers measurable improvements:
Reduced search time: Knowledge workers spend minutes, not hours, finding information. A pharmaceutical company measured a 67% reduction in time-to-answer for technical sales questions.
Better AI accuracy: RAG systems using federated knowledge planes hallucinate less because they retrieve real data from authoritative sources instead of relying on training data.
Lower IT debt: You're not creating another data silo that needs maintenance. Source systems remain sources of truth. Your federated layer is stateless infrastructure.
Faster onboarding: New employees access institutional knowledge without needing to learn which systems contain which information.
Enabled AI workflows: Once you have a federated knowledge plane, you can build intelligent agents that take action across systems—not just search, but workflow automation that spans your entire data landscape.
What breaks if you skip this
Without federated architecture, your AI initiatives hit walls:
- You can't build reliable agents because they can't access the data they need
- RAG implementations hallucinate because context is incomplete
- You waste engineering time building point-to-point integrations between systems
- Compliance teams veto projects because you're replicating sensitive data
- Knowledge workers remain trapped in manual search workflows
The alternative—centralized data lakes—creates different problems. You're now responsible for data freshness, synchronization failures, and duplicated compliance obligations. Every system update requires ETL pipeline maintenance.
Federated knowledge planes avoid these traps by treating source systems as the source of truth and building intelligence in the abstraction layer.
Technical considerations
Query latency: Federated queries are slower than querying a single database. Mitigate with intelligent caching, predictive prefetching of related entities, and parallel query execution across systems.
Schema drift: Source systems change their APIs and data models. Build versioned adapters and automated schema validation to catch breaking changes before they reach production.
Permission complexity: Federated security is hard. A user might have read access to a Salesforce account but not the associated contract in NetSuite. Your gateway must handle these partial-access scenarios gracefully.
Vector embedding freshness: Documents change. Build incremental re-embedding pipelines that update vectors when source content changes. Use webhooks or polling depending on source system capabilities.
When this architecture fits
Federated knowledge planes make sense when:
- Your organization has more than five critical data sources
- Knowledge workers spend significant time searching for information
- You're building AI features that need access to proprietary data
- Compliance requirements prevent centralizing sensitive data
- You want to avoid vendor lock-in on knowledge management platforms
This isn't the right architecture for startups with three systems or organizations where a single source of truth already exists. It's engineering investment that pays off at enterprise scale.
The path forward
Enterprise search has been a solved problem in vendors' slide decks for two decades. In practice, it remains broken because the architecture is wrong.
Federated knowledge planes fix this by respecting how organizations actually work: data stays in specialized systems, and intelligence lives in the abstraction layer that connects them.
You're not building another search product. You're building the knowledge infrastructure that makes AI valuable inside your organization.
Start with your semantic data model. Everything else follows from that foundation.
Related Reading:
- Architecting a centralised enterprise knowledge graph | Blogpost | The WrightyMedia Agency
- Architecting a trusted data foundation | Blogpost | The WrightyMedia Agency
- Beyond the Dashboard: How Enterprise CTOs Can Leverage Next.js and AI-Powered Automation (Make/n8n) to Unify Business Operations and Drive Predictable Growth | Blogpost | The WrightyMedia Agency
Want more on
Growth Systems?
Add this topic to your Custom Digest. Drop your email to get our deepest insights on this exact topic.
Ready to fast-track your business?
We combine enterprise-level technical strategy with your existing business to solve complex blockers and accelerate your growth. Let's build something remarkable.
Partner With UsUp Next
Continue your journey into Growth Systems.
The growth leader's blueprint for composable content velocity
How marketing leaders build composable content systems that bypass engineering queues and accelerate campaign deployment without code.
Unifying RevOps insights with event-driven data planes
How to build an event-driven data plane that delivers real-time RevOps insights and cuts integration costs by 15%.
Decoupling digital experiences for faster marketing agility
How decoupling content from delivery lets marketing teams ship faster, test more, and cut engineering dependencies that slow growth.