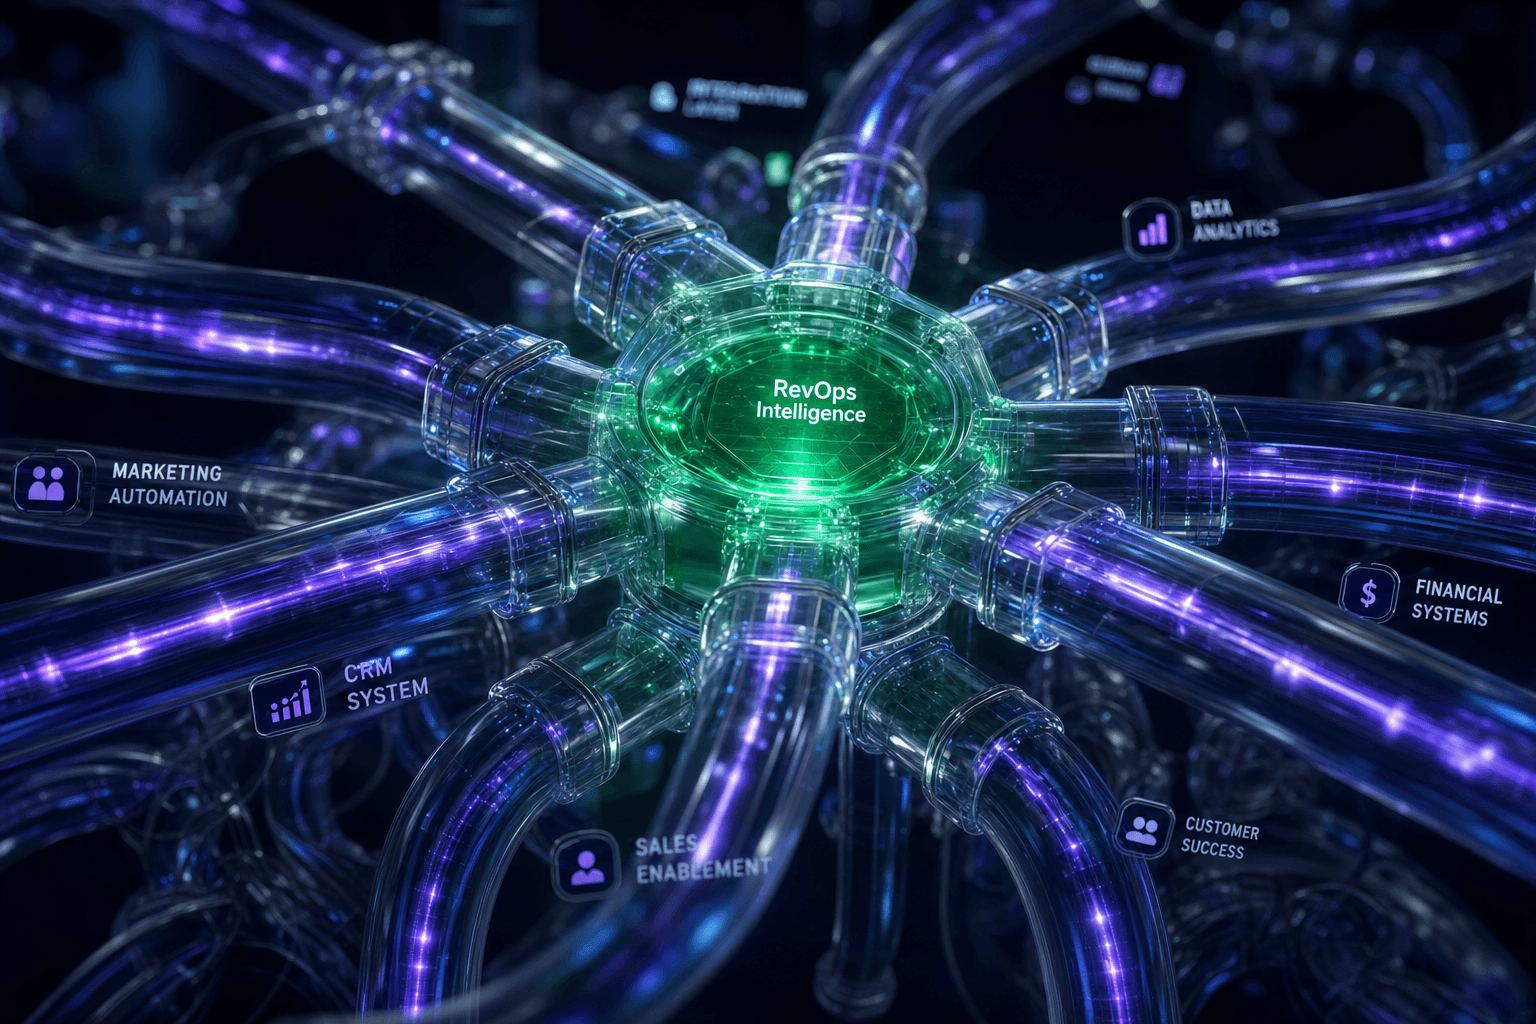
Building event-driven data plane
How to build an event-driven data plane that delivers real-time RevOps insights and cuts integration costs by 15%.
Key Takeaways
- An event-driven data plane eliminates batch delays and delivers real-time RevOps insights for proactive decisions.
- Decoupling data producers from consumers cuts integration costs by 15% and reduces vendor lock-in risks.
- A unified event schema with a central streaming platform creates one consistent source of truth across all revenue systems.
- Real-time event streaming reduces data latency by 25% and strengthens compliance through verifiable audit trails.
Your RevOps data is stuck in silos, forcing your team to react instead of act. An event-driven data plane treats every revenue action as a real-time event, creating a single source of truth that cuts decision lag and integration costs. Here's how to build it.
Your RevOps data sits in silos. CRM updates happen in Salesforce. Marketing automation runs in HubSpot. Financial close happens in NetSuite. Each system holds a fragment of your revenue truth, and none of them talk to each other in real time.
The result? Your strategic decisions lag behind operational reality by hours or days. You're flying blind when market conditions shift. Your data engineers spend weeks building brittle point-to-point integrations that break every time a vendor updates their API.
This isn't a tooling problem. It's an architectural one.
The real cost of fragmented RevOps data
Most enterprise RevOps stacks rely on batch processing and scheduled syncs. A lead converts at 9 AM, but your revenue dashboard doesn't reflect it until the nightly ETL job runs at midnight. By then, your sales team has already made decisions based on stale data.
The damage compounds:
- Manual reconciliation burns engineering time. Your team exports CSVs, writes transformation scripts, and troubleshoots data mismatches instead of building product.
- Point-to-point integrations create technical debt. Every new system requires N+1 custom connections, each with its own failure modes and maintenance overhead.
- Data sprawl increases security surface area. Revenue data gets replicated across multiple databases, each requiring separate governance policies and audit trails.
- Vendor lock-in constrains strategic flexibility. Switching CRMs becomes a six-month migration project because your entire data infrastructure depends on vendor-specific APIs.
The traditional approach optimizes for vendor convenience, not operational agility.
Why event-driven data planes change the equation
An event-driven data plane treats every meaningful RevOps action as an immutable fact published to a central stream. A lead status changes. A deal moves to closed-won. A customer cancels their subscription. Each becomes a timestamped event that flows through a unified infrastructure.
This shifts the paradigm from pull-based batch processing to push-based real-time propagation.
Instead of asking "What changed since I last checked?", your systems receive instant notifications when change occurs. Analytics dashboards update in seconds, not hours. AI models train on fresh data. Automated workflows trigger without polling delays.
The architecture decouples data producers from consumers. Your CRM doesn't need to know about your data warehouse, and your data warehouse doesn't care which CRM you use. Both publish and consume events through a governed interface.
The architecture blueprint
Step 1: Design a universal event schema
Start by mapping every critical revenue event across your stack. What happens when a lead enters the pipeline? When a deal stage changes? When payment terms get renegotiated?
Define a canonical schema for each event type:
- Event ID: Unique identifier for deduplication
- Event type: Standardized name (e.g.,
lead.status_changed,deal.closed_won) - Timestamp: When the event occurred in the source system
- Payload: The actual data change, in a consistent structure
- Metadata: Source system, user context, correlation IDs for tracing
Implement a schema registry to enforce versioning and backward compatibility. When your CRM vendor changes their data model, your event schema insulates downstream consumers from breaking changes.
This isn't about achieving perfect normalization on day one. Start with high-value events—deal lifecycle changes, customer health score shifts, revenue recognition triggers. Expand the schema as operational needs evolve.
Step 2: Deploy an enterprise streaming platform
You need infrastructure that can handle production-grade event volumes with guaranteed delivery and fault tolerance.
Apache Kafka and its managed cloud equivalents (Confluent Cloud, AWS MSK, Azure Event Hubs) provide the durability and throughput required for enterprise RevOps. These platforms persist events to disk, replicate across availability zones, and support horizontal scaling as event volume grows.
Architect your topics around business domains, not source systems. Create separate topics for lead events, opportunity events, customer events, and financial events. This domain-driven approach simplifies access control and makes downstream consumption patterns more intuitive.
Build source connectors for each existing system. Change Data Capture (CDC) tools can stream database changes directly to your event platform without modifying application code. For systems that expose webhooks, write lightweight adapters that translate vendor payloads into your canonical event schema.
Critical: design for idempotency. Network failures and retries mean events might get delivered multiple times. Your consumers must handle duplicate events gracefully by checking event IDs before processing.
Step 3: Build a curated analytical data mart
Raw event streams are perfect for real-time workflows, but analytical queries need denormalized, aggregated views.
Create a separate data mart that consumes events from your streaming platform, applies business logic transformations, and materializes queryable tables optimized for read performance. This is where you join lead events with opportunity events, calculate pipeline velocity metrics, and build customer health scores.
Use stream processing frameworks (Kafka Streams, Flink, Spark Structured Streaming) to perform transformations as events arrive. Maintain rolling aggregations—30-day pipeline conversion rates, quarterly revenue trends, customer lifetime value calculations—that update incrementally with each new event.
Expose this data mart through a virtualization layer that provides a unified SQL or GraphQL interface. Business intelligence tools query this layer without needing to understand the underlying event infrastructure.
Implement strict access controls at the virtualization layer. Revenue data often carries compliance requirements. Row-level security ensures sales reps see their territories, finance sees everything, and external auditors get read-only access to specific time ranges.
The operational payoff
This architecture delivers measurable improvements:
Latency drops by 25%. Revenue insights that took 6 hours now arrive in under 90 seconds. Sales leadership sees pipeline changes before the deal review meeting starts, not after.
Integration costs fall by 15%. You stop building and maintaining custom connectors for every vendor pair. New systems plug into the event stream, and existing consumers automatically see the data.
Data lineage becomes auditable. Every event carries a complete provenance trail. Compliance teams can trace revenue recognition back to the original CRM activity, timestamped and immutable.
Vendor switching becomes tactical. Migrating from one CRM to another means updating a single source connector. Downstream consumers continue operating without code changes.
The compounding effect matters more than individual metrics. When your data infrastructure removes friction, your team ships faster. Product decisions get made on current reality, not last week's snapshot. RevOps automation scales without engineering bottlenecks.
What this means for CTOs
You're choosing between two architectural paths. The traditional approach optimizes for initial implementation speed—spin up point-to-point integrations, run nightly batch jobs, hope the data stays mostly consistent.
The event-driven approach requires more upfront design. You need to define schemas, deploy streaming infrastructure, and educate your team on eventual consistency patterns.
But the traditional path compounds technical debt with every new integration. The event-driven path compounds value with every new consumer. Each new analytics dashboard, each new automated workflow, each new AI model becomes easier to build because the data foundation already exists.
The question isn't whether to build an event-driven data plane. It's whether you build it proactively, or reactively after your tenth integration breaks in production and your board asks why revenue numbers don't reconcile.
The enterprises that treat real-time data infrastructure as a strategic asset move faster than competitors still stitching together point-to-point connections. The architectural choice you make today determines your operational velocity for the next five years.
Related Reading:
- Implementing AI-powered operational intelligence for proactive decision making
- Beyond the Dashboard: How Enterprise CTOs Can Leverage Next.js and AI-Powered Automation (Make/n8n) to Unify Business Operations and Drive Predictable Growth | Blogpost | The WrightyMedia Agency
- Unifying customer data for accelerated RevOps pipeline conversion
Want more on
Growth Systems?
Add this topic to your Custom Digest. Drop your email to get our deepest insights on this exact topic.
Ready to fast-track your business?
We combine enterprise-level technical strategy with your existing business to solve complex blockers and accelerate your growth. Let's build something remarkable.
Partner With UsUp Next
Continue your journey into Growth Systems.
Deploying for composable content
How decoupling content from delivery lets marketing teams ship faster, test more, and cut engineering dependencies that slow growth.
Deploying resilient data pipelines for sovereign AI
Build self-hosted AI data pipelines that eliminate vendor lock-in, ensure data sovereignty, and cut RevOps costs for enterprise leaders.
Designing sovereign data plane for enterprise AI
How to build enterprise-controlled AI infrastructure that cuts regulatory risk and protects your intellectual property from vendor exposure.