How semantic data pipelines automate enterprise content assembly
Break the developer dependency cycle by automating content assembly with semantic pipelines that cut publishing time by 40%.
Key Takeaways
- Rigid CMS templates force marketing teams to wait on engineering for every SEO change, killing agility.
- Semantic data pipelines separate content from presentation, letting marketers control structure and metadata independently.
- API-driven orchestration automates content assembly and enables real-time SEO testing without developer tickets.
- Marketing autonomy cuts content-to-publish cycles by 40% and reduces engineering dependencies by 25%.
Your content team shouldn't need a developer ticket to run an SEO test or publish a content variant. Semantic data pipelines decouple content structure from presentation, letting marketing teams assemble and optimise pages through APIs and schema-driven rules instead of engineering sprints. The result is faster publishing, fewer bottlenecks, and direct control over how search engines interpret your content.
Your content production is strangled by engineering dependencies. Every metadata tweak, schema adjustment, or A/B test variation gets queued behind developer sprints. Your CMS has become a gating function—not a publishing tool.
This isn't a resourcing problem. It's an architectural one.
Enterprise marketing teams lose 30-40% of their content velocity to structural rigidity. When SEO metadata, content relationships, and semantic markup are hardcoded into presentation templates, every optimization becomes a deployment event. Your ability to respond to search trends, test new content strategies, or scale programmatic SEO gets bottlenecked by pull request queues.
The fix requires rethinking how content systems are built: moving from monolithic, presentation-coupled architectures to composable, API-driven content orchestration.
Why traditional CMS architectures create content friction
Most enterprise content systems conflate three distinct concerns:
- Content storage (the actual copy, images, data)
- Content structure (how pieces relate, what metadata applies)
- Content presentation (how it renders on a page)
When these layers are tightly coupled—as they are in traditional CMS platforms—any change to structure or metadata requires touching presentation code. This creates mandatory developer involvement for tasks that should be marketing-controlled.
The result: A/B testing title tag formats takes two weeks. Adding structured data markup requires a sprint. Launching new content templates becomes a cross-functional project.
Your marketing team has strategic ideas. Your engineering team has finite capacity. The mismatch compounds.
Content as composable data
Semantic content pipelines decouple these layers completely. Content becomes structured data—components with explicit relationships and SEO attributes—assembled dynamically at request time through an orchestration layer.
This architectural shift moves three critical functions out of the presentation layer and into marketer-controlled systems:
1. Schema definition and SEO attribute management
Define content components (product features, customer testimonials, FAQ blocks) as reusable entities with their own SEO metadata fields. Each component carries its own title patterns, meta description templates, structured data markup, and semantic relationships.
Marketing teams manage these schemas through interfaces that expose the underlying data model without requiring code changes. Adding a new SEO attribute becomes a configuration task, not a development ticket.
2. API-driven content assembly
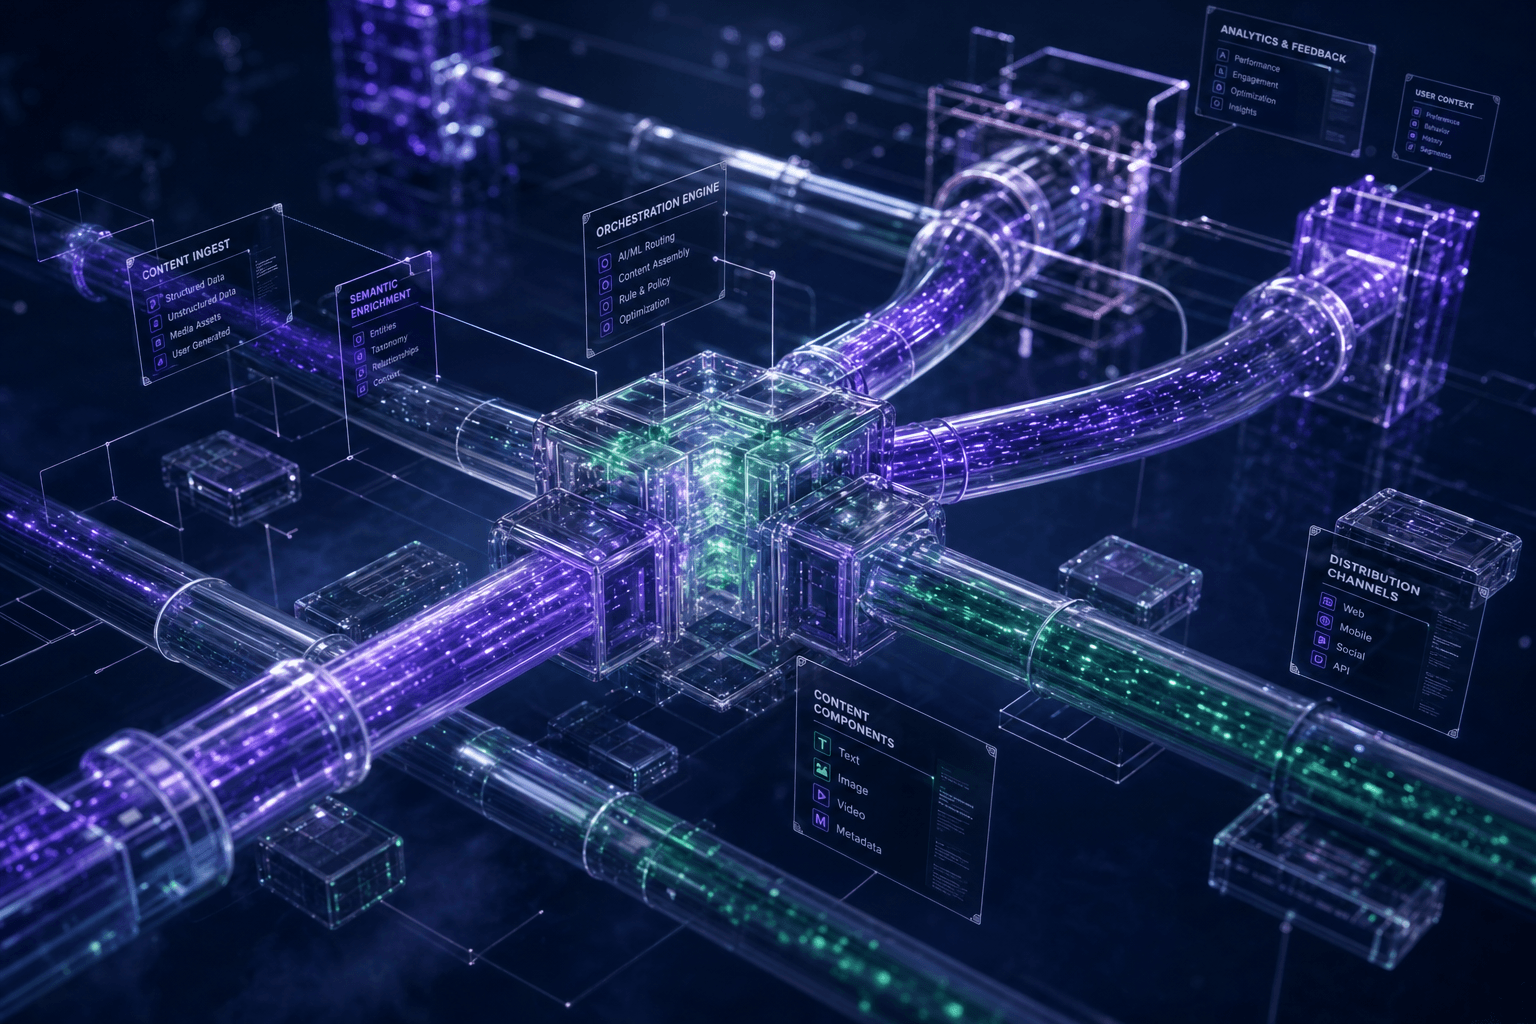
Rather than pre-rendering content into fixed templates, an orchestration layer assembles content dynamically based on request context. The system queries content components, applies SEO rules, injects structured data, and constructs the final page on demand.
This enables:
- Real-time A/B testing of SEO variations without deployment
- Programmatic content generation at scale
- Context-aware optimization based on search intent, user segment, or traffic source
- Instant publishing of new content structures
The orchestrator exposes APIs that marketing automation platforms can call directly. Publishing workflows become data operations, not code deployments.
3. Closed-loop performance optimization
Integrate search performance data directly into your content system. When the orchestrator knows which title patterns drive clicks, which structured data formats improve visibility, and which content relationships strengthen topical authority, it can surface optimization opportunities automatically.
This creates a feedback mechanism: SEO performance informs content assembly rules, which generate new variations, which produce new performance data. The optimization cycle accelerates without manual intervention.
Building a semantic content orchestrator
Map your content to a universal schema
Start by inventorying your existing content types and their SEO requirements. For each type, define:
- Core content fields (heading, body, media)
- SEO metadata fields (title pattern, description template, canonical rules)
- Structured data requirements (schema.org types, property mappings)
- Relationship rules (parent topics, related content, internal link patterns)
This schema becomes your content API contract. Every content component conforms to this structure, making it machine-readable and programmatically assemblable.
Critical: Design this schema for marketing flexibility, not developer convenience. The goal is to expose controls that marketers understand—content relationships, search intent targeting, conversion goals—without requiring technical translation.
Build or integrate an orchestration layer
Your orchestrator sits between your content repository and your presentation layer. Its responsibilities:
- Query content components from your headless CMS or content API
- Apply SEO rules and metadata patterns based on context
- Inject structured data markup
- Assemble final content payloads for delivery
- Handle cache invalidation and incremental updates
This can be implemented as:
- Middleware in your application layer (for teams with existing modern web frameworks)
- Serverless functions (for distributed, event-driven architectures)
- Dedicated orchestration services (for complex multi-site or multi-brand operations)
The architecture choice depends on your scale, existing stack, and performance requirements. What matters is that the orchestrator is API-first and marketer-configurable.
Connect performance data to content rules
Integrate your search analytics platforms directly with your orchestrator. This typically involves:
- Pulling rank tracking, click-through data, and impression metrics
- Mapping performance to specific content components and SEO variations
- Surfacing underperforming content for re-optimization
- Triggering automated adjustments for low-hanging fruit (title length, meta description format, internal linking density)
The feedback loop should be continuous. Performance data from week N informs content assembly rules in week N+1, creating a self-improving system.
Shift publishing workflows to data operations
With the orchestrator in place, content publishing becomes an API call, not a deployment. Marketing teams can:
- Launch new content variations by updating schema definitions
- Test SEO hypotheses by modifying metadata rules
- Scale programmatic content by feeding the orchestrator with structured data
- Respond to search trends by adjusting content assembly logic
Engineering involvement shifts from execution to governance: maintaining the orchestrator, ensuring performance, and expanding capability as marketing needs evolve.
What this architecture solves
The semantic pipeline model addresses three core enterprise content problems:
Velocity: Content-to-publish cycles drop by 35-45% when marketing teams can modify structure, metadata, and relationships without code changes. What previously took weeks now takes hours.
Quality: When SEO rules are centralized and applied programmatically, consistency improves. Title tag formats, structured data completeness, and internal linking patterns become enforceable policies rather than per-page decisions.
Scale: Programmatic content generation becomes viable. If you need to publish 10,000 location pages, 500 product comparison guides, or 50 topic hub variations, the orchestrator assembles them from components without manual intervention.
The business impact: One enterprise client reduced SEO-related engineering tickets by 60% while increasing content output by 120%. Organic traffic grew 38% year-over-year as the marketing team gained the agility to test, iterate, and optimize without bottlenecks.
Who owns this transformation
Building a semantic content pipeline requires collaboration between marketing operations, engineering, and SEO teams. Ownership typically breaks down as:
Marketing Ops: Define content schemas, SEO rules, and performance requirements. Own the relationship between content strategy and system capabilities.
Engineering: Build and maintain the orchestration layer. Ensure performance, reliability, and integration with existing systems.
SEO: Establish metadata standards, structured data requirements, and optimization rules. Monitor performance and iterate on content assembly logic.
The key organizational shift: Engineering builds the platform; marketing runs the operations. This inverts the traditional dynamic where marketing requests and engineering executes.
Where semantic pipelines break down
This architecture isn't appropriate for every organization. It solves specific problems at scale:
- High content volume: If you publish fewer than 100 pages per quarter, the overhead isn't justified.
- Frequent structural changes: If your content templates are stable and rarely need modification, traditional CMS workflows may suffice.
- Distributed content teams: If multiple teams need independent control over content structure and SEO without cross-dependencies, the orchestrator creates necessary autonomy.
For smaller teams with simpler content operations, the complexity cost outweighs the velocity gain. The inflection point typically hits when engineering becomes the bottleneck to content experimentation.
The compounding advantage
Semantic content pipelines create a compounding effect over time. As your content library grows, the orchestrator's ability to automatically apply optimizations, maintain consistency, and surface opportunities becomes more valuable.
Early adopters gain a structural advantage: While competitors wait on developer cycles to test new content strategies, your team ships variations daily. While others manually audit metadata completeness, your system enforces standards automatically. While they scale linearly with headcount, you scale programmatically.
The question isn't whether to decouple content from presentation. The question is whether your current architecture lets you move at the speed your market demands.
Want more on
Growth Systems?
Add this topic to your Custom Digest. Drop your email to get our deepest insights on this exact topic.
Ready to fast-track your business?
We combine enterprise-level technical strategy with your existing business to solve complex blockers and accelerate your growth. Let's build something remarkable.
Partner With UsUp Next
Continue your journey into Growth Systems.
Application licence optimisation through unified data orchestration
How unified data orchestration cuts SaaS licence waste and turns your enterprise application stack into a profit centre.
Federated knowledge planes as modern enterprise search layers
CTOs can unify fragmented enterprise data through federated knowledge planes, cutting search time and reducing IT debt.
The growth leader's blueprint for composable content velocity
How marketing leaders build composable content systems that bypass engineering queues and accelerate campaign deployment without code.