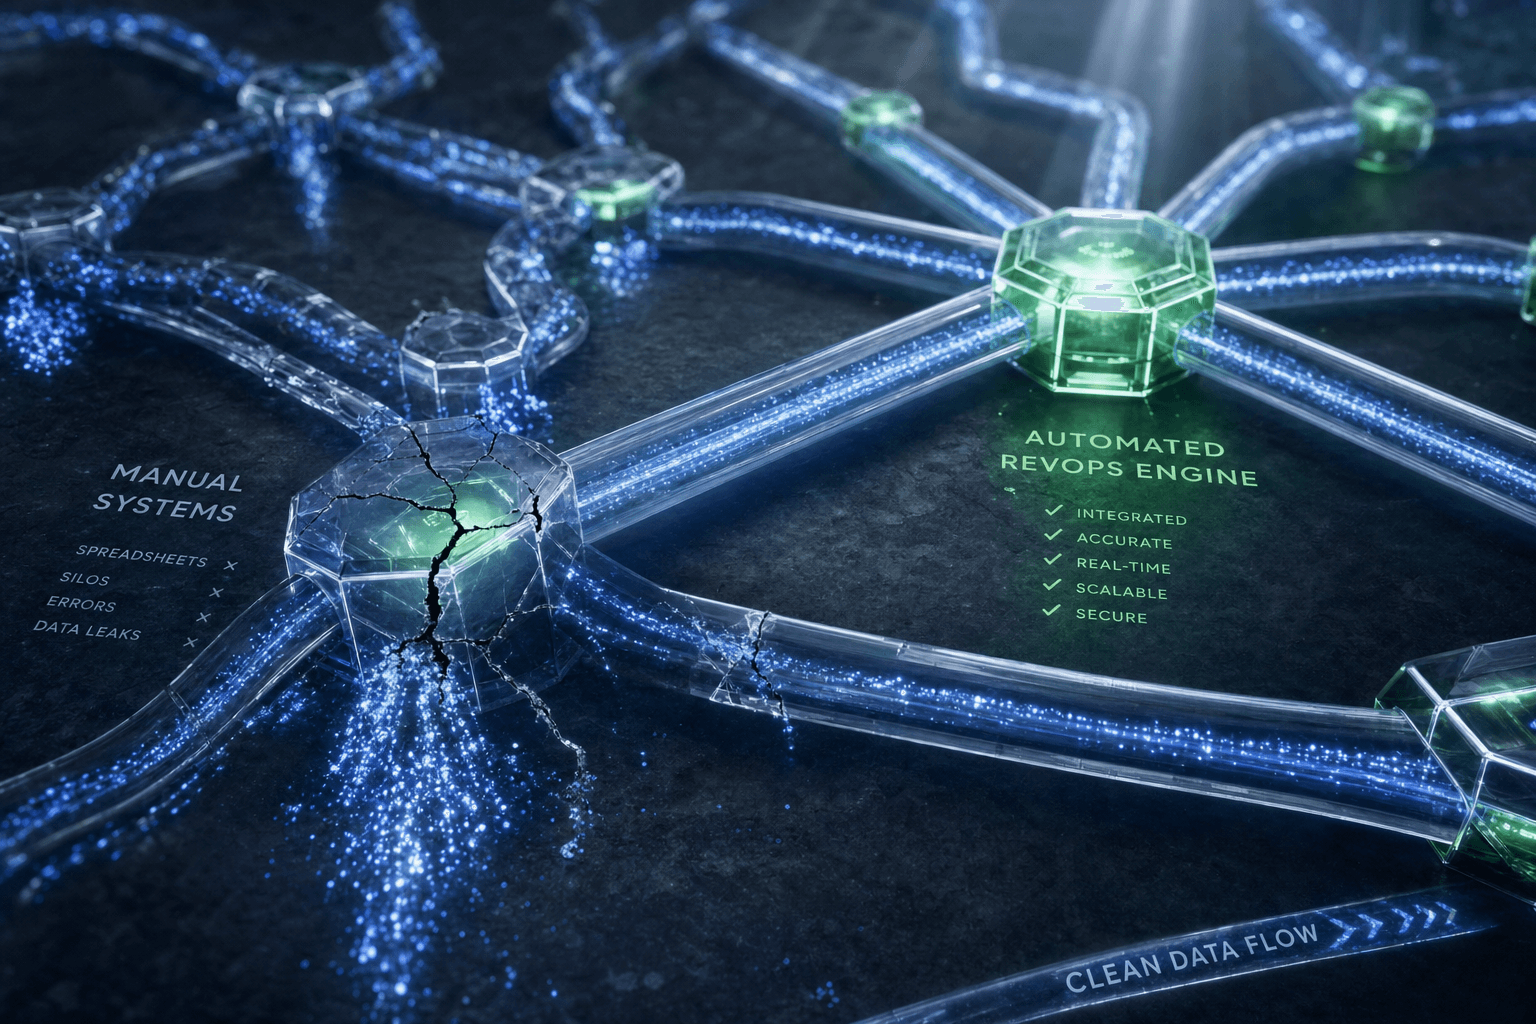
Stop pipeline leaks with automated data flows
Learn how automated data flows stop pipeline leaks, cut manual work, and give RevOps teams clean, reliable data for faster sales cycles.
Key Takeaways
- Manual data entry costs you money, slows deals, and creates pipeline leaks you can't see.
- Event-driven automation replaces reactive fixes with proactive data orchestration across your entire tech stack.
- Real-time data synchronisation gives your teams a single source of truth for every lead and opportunity.
- Clean pipeline data accelerates sales cycles, improves forecasting accuracy, and directly increases revenue.
Manual data entry and broken integrations bleed revenue from your sales pipeline. RevOps teams waste hours chasing missing lead updates, cleaning duplicate records, and explaining why forecasts never match reality. Automated data flows fix this by syncing your CRM, marketing platforms, and ERP systems in real time—no human intervention required.
Your RevOps team is bleeding revenue. Not through bad strategy or poor territory planning, but through something far more insidious: data fragmentation.
Every manual CRM entry, every delayed lead handoff, every sync error between your marketing automation platform and sales system creates microscopic leaks. Individually, they're annoying. Collectively, they're devastating to your quarterly numbers.
The average B2B sales team loses 18-23% of qualified leads to routing delays alone. Another 15-20% of pipeline value evaporates from inconsistent data between systems. Your forecasts become fiction. Your reps waste hours chasing ghost opportunities or duplicating work already completed.
This isn't a CRM problem. It's an architecture problem.
Why point-to-point integrations fail at scale
Most RevOps stacks evolved organically. Sales bought Salesforce. Marketing added HubSpot. Customer success insisted on Gainsight. Finance demanded an ERP connection.
Each integration was built in isolation. Marketing to sales: one connector. Sales to finance: another. Service to sales: a third. You end up with a brittle web of dependencies where a single field change can break three downstream systems.
This creates four critical failure modes:
Data latency: Manual exports and batch syncs mean lead information arrives 4-48 hours late. Your SDRs call prospects who already bought from competitors.
Transformation errors: Each system stores contact data differently. Phone number formats, address fields, custom properties—all require translation. Manual mapping introduces mistakes that compound across your stack.
No single source of truth: When HubSpot shows 487 open opportunities worth $12.3M and Salesforce reports 503 opportunities worth $11.8M, which number goes in your board deck?
Zero auditability: When a deal mysteriously disappears from your pipeline, good luck tracing which integration failed and when.
You can't scale revenue operations on this foundation. You need a different architecture.
The event-driven data orchestration model
Event-driven architecture treats every meaningful change in your RevOps stack as a discrete event that triggers automated workflows.
A prospect fills out a form. Event fired. Lead scoring threshold crossed. Event fired. Opportunity moves to negotiation stage. Event fired. Contract signed. Event fired.
Each event triggers a series of automated actions across your tech stack, governed by centralized business logic you control.
Here's what this looks like in practice:
Layer 1: Event capture
Every source system emits events when data changes. Webhooks from your CRM, form submissions from your website, status updates from your payment processor. These feed into a central orchestration platform.
Layer 2: Business logic and routing
Your orchestration layer applies transformation rules, enrichment logic, and routing decisions. A new enterprise lead from the finance vertical gets assigned to your enterprise SDR team, tagged with industry-specific attributes, and enrolled in a targeted nurture sequence—all in real-time.
Layer 3: Destination sync
Transformed, enriched data pushes to every system that needs it. CRM, marketing automation, analytics warehouse, Slack notifications for high-value accounts. All systems receive consistent, properly formatted data simultaneously.
Layer 4: Monitoring and reconciliation
Continuous health checks verify data arrived correctly. Automated alerts flag discrepancies before they become forecast errors.
This isn't theoretical. Financial services firms processing 50,000+ leads monthly use this exact architecture to maintain 99.7% data accuracy between marketing and sales systems.
Building your RevOps automation layer
Implementing event-driven data flows doesn't require ripping out your existing stack. You're adding an orchestration layer on top.
Map your critical data journeys
Start with revenue impact, not technical complexity.
Identify the five data flows that most directly affect pipeline velocity:
- Lead capture to assignment (target: under 5 minutes)
- Opportunity creation to initial outreach (target: same business day)
- Stage progression updates across sales and finance (target: real-time)
- Closed-won to customer success handoff (target: within 1 hour)
- Contract value updates to revenue recognition (target: immediate)
For each journey, document:
- Source system and trigger event
- Required data transformations
- Target systems and format requirements
- Current latency and error rates
- Business impact of delays or failures
This mapping exercise typically reveals 60-80% of your pipeline leakage concentrates in just 3-4 data flows.
Design your automation workflows
Build workflows that respond to events, not batch schedules.
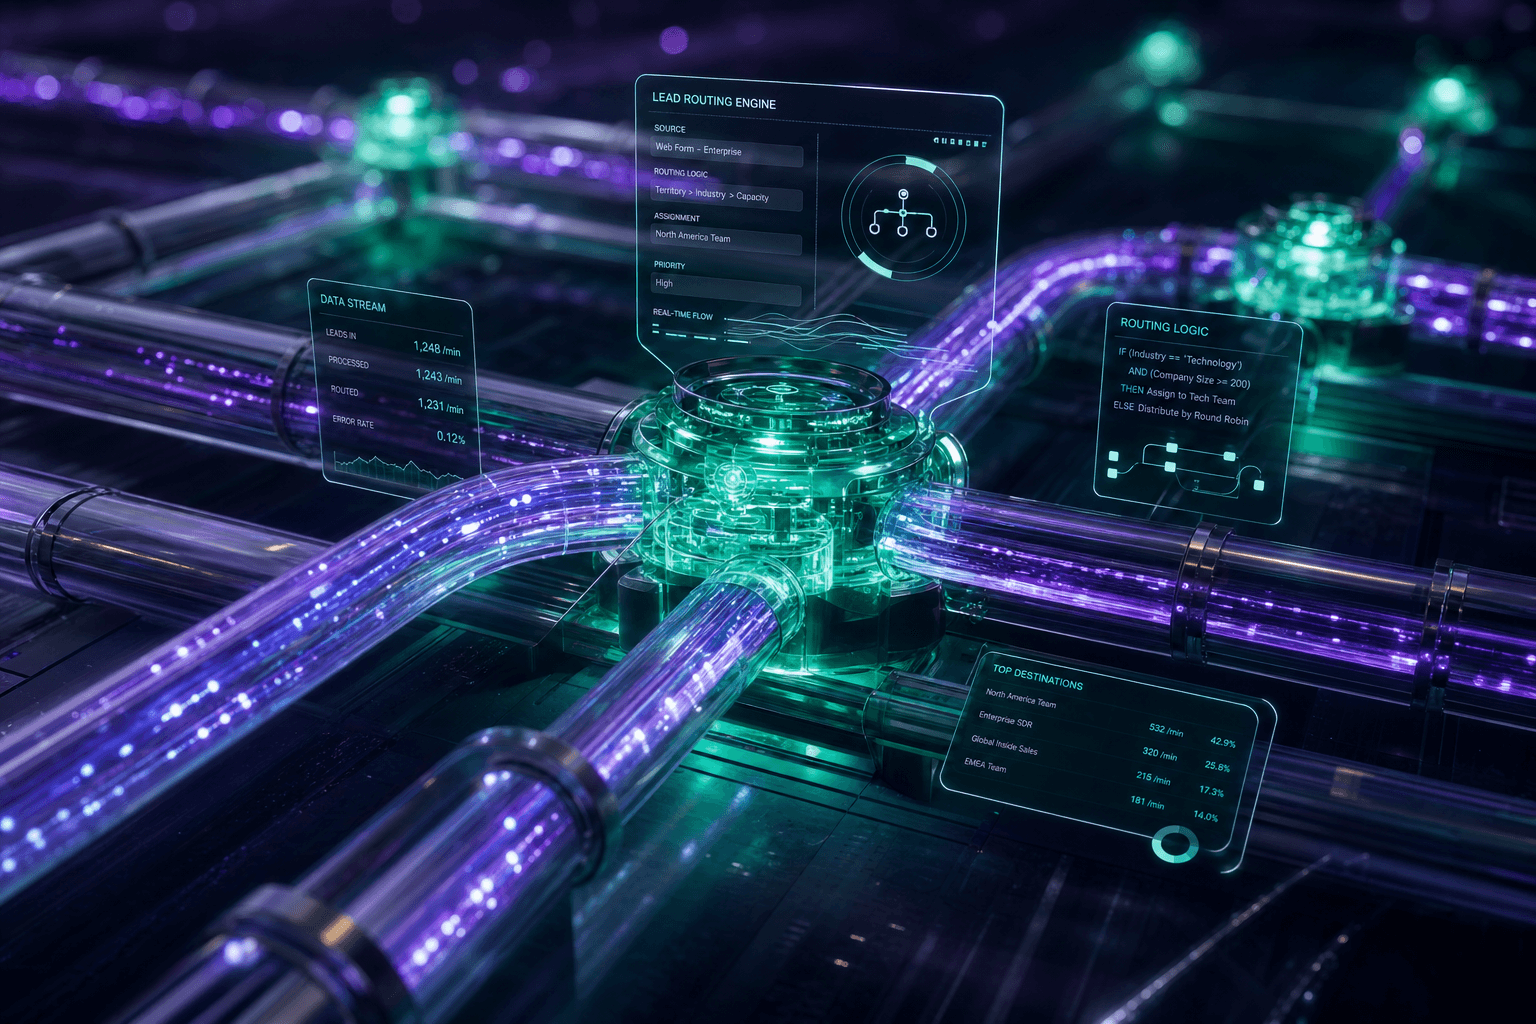
A properly designed lead routing workflow looks like this:
Trigger: New lead record created in HubSpot
Condition checks: Lead score above 50, company size over 500 employees, country in supported territory list
Enrichment: Pull firmographic data from your data provider, check against existing account records for potential duplicates
Routing logic: Assign to appropriate SDR based on territory, industry vertical, and current workload
Actions: Create Salesforce lead, assign owner, send Slack notification, add to outreach sequence, log activity in analytics warehouse
Validation: Confirm record creation in Salesforce, verify field mapping accuracy
The entire workflow executes in 30-90 seconds. No manual handoffs. No data entry. No opportunity for human error.
Your automation platform becomes the central nervous system for RevOps, translating events into coordinated actions across your entire tech stack.
Implement continuous data quality monitoring
Automation moves bad data faster than humans can. You need active monitoring to catch problems before they corrupt your pipeline.
Establish four monitoring layers:
Workflow health dashboards: Track execution success rates, error types, and processing latency for every automated workflow. Set alerts for any workflow dropping below 98% success rate.
Data reconciliation checks: Run automated comparisons between systems every 15 minutes. Lead counts, opportunity values, stage distributions should match within defined tolerances.
Field-level validation: Monitor for impossible values, format inconsistencies, or missing required fields. A blank email address or negative deal value indicates upstream problems.
Business metric correlation: Track how data quality metrics correlate with revenue outcomes. If lead response time climbs from 5 minutes to 45 minutes, what happens to conversion rates?
Most RevOps teams discover 20-30 previously unknown data quality issues within the first week of monitoring.
Build gradual, test incrementally
Don't automate everything simultaneously.
Start with your highest-impact, lowest-complexity workflow. Typically this is lead routing or opportunity stage synchronization. Run it in parallel with your existing manual process for 2-3 weeks.
Compare outcomes:
- Speed: How much faster does automation route leads?
- Accuracy: Error rate compared to manual entry?
- Coverage: Any edge cases the automation misses?
Refine the workflow based on real data, then deprecate the manual process.
Move to your second-priority workflow. Repeat.
This incremental approach builds team confidence and allows you to prove ROI before making larger architectural investments.
The technical architecture
You need three technical components:
1. Workflow automation platform
Low-code tools that connect to your existing systems via APIs and webhooks. Look for platforms with:
- Pre-built connectors to your core RevOps stack
- Visual workflow builders that don't require engineering resources
- Robust error handling and retry logic
- Execution logs for debugging and compliance
This becomes your orchestration layer. Everything routes through it.
2. Data warehouse
A centralized repository for historical data from all systems. This isn't optional. You need a source of truth for analytics, reporting, and training machine learning models for lead scoring or churn prediction.
Your warehouse receives a copy of every event that flows through your orchestration layer. This creates an immutable audit trail and enables sophisticated cross-system analysis impossible with individual CRM reports.
3. Monitoring and observability tools
Dashboards that surface workflow health, data quality metrics, and business impact. Many automation platforms include basic monitoring, but dedicated observability tools provide deeper insights into system-wide performance.
Total implementation cost for a mid-market company: $30,000-$60,000 annually for tooling, plus 200-400 hours of internal RevOps time for initial setup and ongoing refinement.
Expected business outcomes
RevOps automation delivers measurable impact across four dimensions:
Cost reduction: Teams report 40-60% reduction in time spent on manual data entry and cleanup. For a 10-person RevOps team, that's 2,000-3,000 hours annually redirected to strategic work.
Pipeline velocity: Automated routing and real-time sync cut lead response time by 65-80%. Faster response directly correlates with higher conversion rates—studies show contact rates drop 50% if you wait 10 minutes versus 5 minutes.
Forecast accuracy: Clean, consistent data improves forecast accuracy by 20-35 percentage points. CFOs can model scenarios and resource allocation with actual confidence in the numbers.
Revenue impact: The combined effect of faster routing, better data quality, and improved forecasting typically produces 12-18% increases in win rates within two quarters.
For a company with $50M ARR, that's $6-9M in additional revenue from the same marketing spend and sales team size.
Common implementation pitfalls
Three mistakes kill most RevOps automation projects:
Automating broken processes: If your manual lead routing process assigns leads randomly because territory rules are unclear, automation just executes bad assignments faster. Fix the process logic first.
Insufficient change management: Your sales team needs to trust the automation. That requires transparency about how assignments work, quick resolution of edge cases, and clear escalation paths when the system makes mistakes.
Over-engineering early: Don't build complex machine learning models for lead scoring before you've automated basic lead routing. Start simple, prove value, then add sophistication.
The teams that succeed treat automation as a continuous improvement program, not a one-time implementation project.
Why this matters now
RevOps complexity grows exponentially with company size. A 50-person company might manage 5-7 core systems. A 500-person company juggles 30-40. A 5,000-person enterprise often exceeds 200.
Manual integration strategies that worked at $10M ARR break completely at $50M. By $100M, you're in crisis.
Companies that automate data flows early create compounding advantages. Clean data enables better segmentation. Better segmentation improves conversion rates. Higher conversion rates justify more marketing spend. More marketing spend requires more sophisticated routing and territory management. All of this becomes impossible without automated data orchestration.
Your competitors are already building this. The question isn't whether to automate RevOps data flows. It's whether you'll do it before pipeline leakage becomes a existential revenue problem.
Want more on
Growth Systems?
Add this topic to your Custom Digest. Drop your email to get our deepest insights on this exact topic.
Ready to fast-track your business?
We combine enterprise-level technical strategy with your existing business to solve complex blockers and accelerate your growth. Let's build something remarkable.
Partner With UsUp Next
Continue your journey into Growth Systems.
Internalise critical growth system APIs
Learn how to audit, encapsulate, and progressively internalise third-party growth APIs to cut vendor lock-in and accelerate feature deployment.
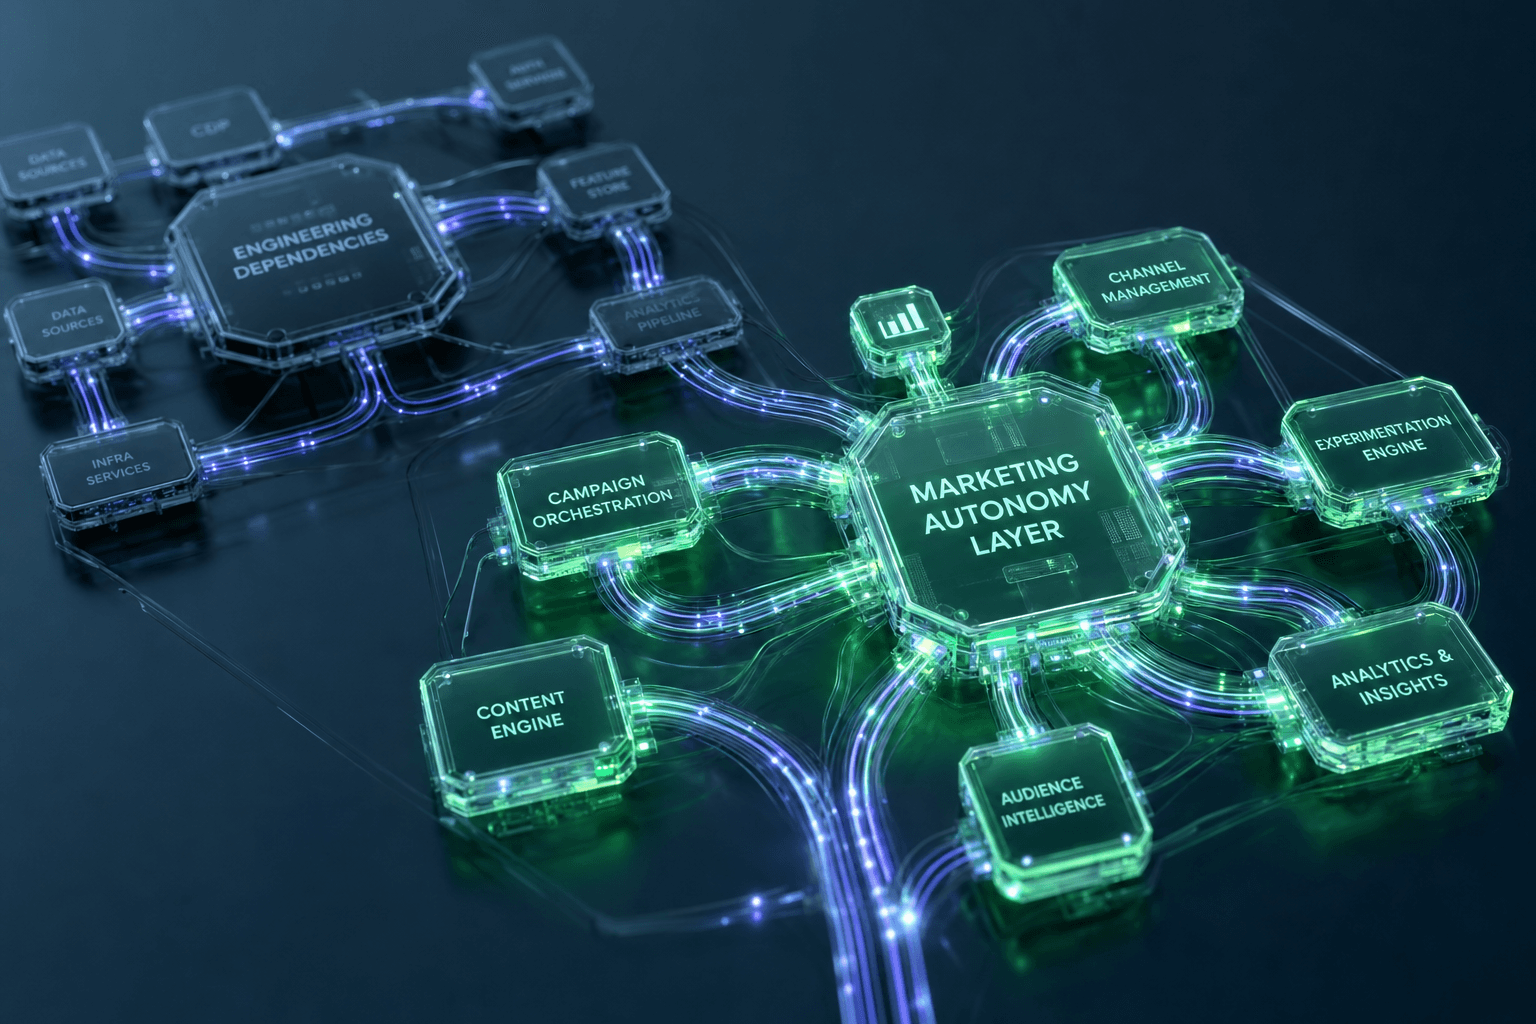
Cutting marketing ops dependencies on engineering cycles
Cut marketing's reliance on engineering queues by decoupling content, SEO, and campaigns through headless platforms and automated workflows.
Automating lead routing for faster sales cycles
Learn how event-driven automation cuts lead response times and stops revenue leaking through manual routing bottlenecks.