The CTO's blueprint for securing enterprise data sovereignty
Learn how to build a sovereign data plane that cuts vendor costs, eliminates compliance risks, and gives you complete control over critical business data.
Key Takeaways
- Enterprise data fragmented across SaaS platforms creates compliance risks and prohibitive egress costs.
- A sovereign operational data plane decouples data ownership from vendor infrastructure and eliminates lock-in.
- API-first connectors and a canonical data model create a unified, enterprise-owned data repository.
- Direct control over your data fabric cuts IT debt, strengthens security, and accelerates decision-making.
Enterprise data scattered across multiple SaaS platforms creates compliance gaps and locks you into expensive vendor dependencies. You can't make fast decisions when your critical business intelligence sits in systems you don't control. Reclaiming full ownership of your operational data is now a technical requirement, not a strategic choice.
The fragmented data problem silently eroding enterprise value
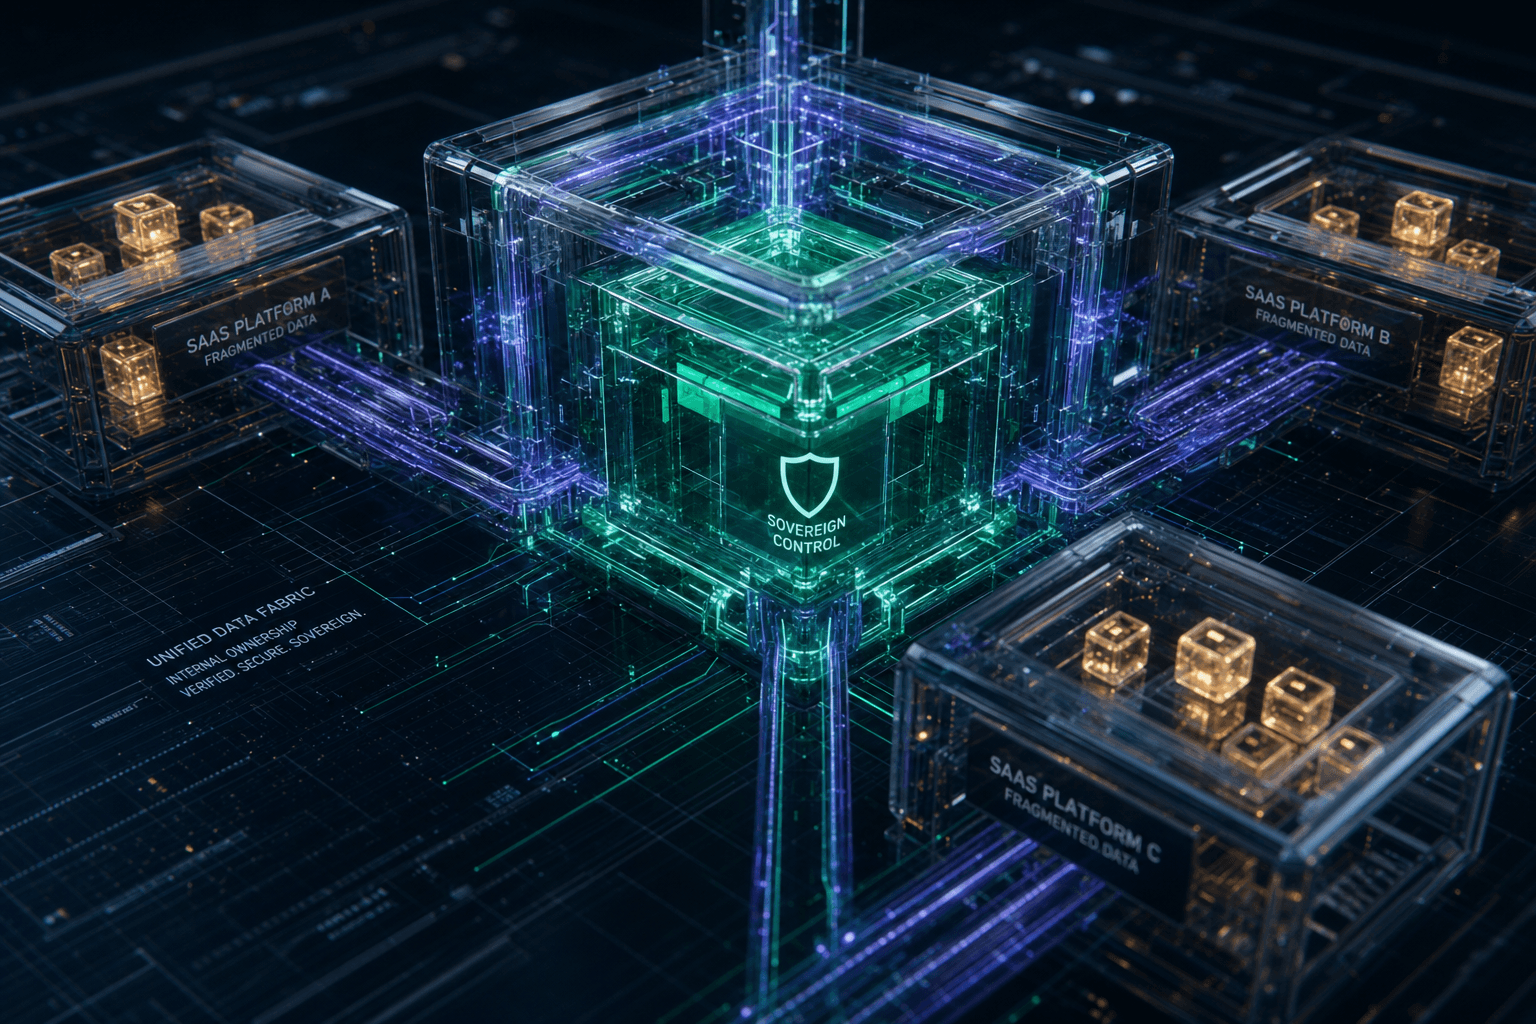
Your critical business intelligence is scattered across a dozen SaaS platforms right now. Each vendor holds a piece of your operational truth—customer interactions in one system, financial data in another, product analytics somewhere else entirely.
This isn't just an inconvenience. It's a structural liability that accumulates compounding costs.
Every time you need to extract data for analysis, you pay egress fees. Every integration between systems creates another maintenance burden. Every vendor contract renewal gives you less negotiating power because migrating away means navigating their data extraction maze.
The compliance exposure grows daily. You can't audit what you don't fully control. GDPR, CCPA, and industry-specific regulations demand clear data lineage and custody. When your data lives in vendor infrastructure, you're trusting their security posture, their backup procedures, their incident response.
For CTOs building for the next decade, this distributed ownership model isn't sustainable. The IT debt accumulates faster than you can pay it down. Your data science team can't build reliable models when the training data exists in six different schemas across five different platforms. Your engineering velocity slows because every new feature requires negotiating with multiple API rate limits and data formats.
The question isn't whether to address this. It's how quickly you can execute before the technical debt becomes insurmountable.
The shift to sovereign operational data infrastructure
The solution requires moving from vendor-dependent data storage to enterprise-owned data sovereignty.
This means building a unified operational data plane where you control the entire lifecycle—ingestion, storage, transformation, access, and deletion. Not as a mirror or cache of vendor data, but as the authoritative source.
The architectural principle is straightforward: decouple data ownership from application vendors. Your CRM vendor provides workflow tools and UI, but your customer data lives in your infrastructure. Your marketing automation platform triggers campaigns, but the behavioral data flows into your data fabric first.
This inverts the traditional SaaS relationship. Tools become interchangeable interfaces to your data rather than proprietary silos that hold your information hostage.
The business impact is immediate. Egress costs drop to zero when you're querying your own databases. Vendor negotiations shift because switching costs decrease dramatically. Compliance audits become manageable when you have complete visibility into data flows and storage.
Your data science and AI initiatives accelerate because training data is available in consistent formats without waiting for vendor API quotas or dealing with rate limits. Real-time analytics become feasible when you're not constantly ETL-ing data between systems.
Most importantly, you regain strategic flexibility. New market opportunities don't require six months of integration work. Your architecture adapts because data access isn't bottlenecked by vendor partnerships.
The three-layer architecture for data sovereignty
Layer one canonical data modeling
Start by defining your single source of truth. This is a canonical data model covering all core business entities—customers, products, transactions, interactions, and their relationships.
The model must be vendor-agnostic. If your CRM calls something a "lead" and your marketing platform calls it a "prospect," you decide the authoritative term and structure. Every field has a clear definition. Every relationship has explicit cardinality.
This isn't documentation for its own sake. This model becomes the schema for your operational database. Every system that needs customer data pulls from this structure, not from Salesforce's proprietary format.
Build this incrementally. Start with your highest-value entities—usually customer records and transaction data. Map existing vendor fields to your canonical structure. Identify conflicts and redundancies now rather than discovering them during migration.
The canonical model eliminates integration spaghetti. New tools conform to your structure instead of you building custom connectors for each vendor's quirks.
Layer two unified data ingestion
With your data model defined, build the extraction layer. This is an API-first connector framework that systematically pulls data from existing SaaS platforms into your infrastructure.
Prioritize based on data criticality and update frequency. Customer interaction data might need near-real-time sync. Historical financial records can migrate in batches overnight.
For each source system:
- Identify the extraction method: Does the vendor provide webhooks for real-time events? A bulk export API? Only CSV downloads?
- Map vendor fields to canonical model: Handle type conversions, null values, and edge cases explicitly
- Implement idempotent ingestion: Ensure the pipeline can recover from failures without creating duplicates
- Build validation checks: Verify data completeness and flag anomalies before they propagate
- Log every transformation: Create audit trails showing how raw vendor data became canonical records
This layer runs continuously. It's not a one-time migration but an ongoing sync that maintains your sovereign copy until you fully decommission vendor storage.
Start with read-only extraction. Don't attempt bidirectional sync initially—that complexity can wait until your data fabric is proven stable.
Enterprise data fabric deployment
Now deploy your operational data store. This is where your canonical data lives permanently.
You have two deployment options:
Self-hosted infrastructure: Complete control, zero vendor dependency, but requires operational expertise. You manage backups, scaling, security patches, and high availability.
Dedicated cloud infrastructure: Rent compute and storage from AWS, GCP, or Azure, but deploy your own database instances. You control the data plane while outsourcing infrastructure management.
Avoid "managed database services" that create new vendor lock-in. Services like DynamoDB or Cosmos DB just trade one dependency for another. Use portable technologies—PostgreSQL, MySQL, or modern analytical databases that you could migrate between providers.
Key architectural requirements:
- Row-level security: Implement granular access controls so each application sees only authorized data
- Encryption at rest and in transit: Your data sovereignty is meaningless if storage isn't secured
- Point-in-time recovery: Backups every 15 minutes minimum, tested monthly
- Geographic redundancy: Multi-region deployment if compliance requires data residency
- Performance monitoring: Track query patterns to optimize indexes before latency becomes an issue
This infrastructure becomes your competitive moat. Competitors replicating your product features is straightforward. Competitors building your institutional data assets is impossible.
Migration execution strategy
Don't attempt a big-bang migration. That path leads to months of frozen development and inevitable rollbacks.
Instead, run dual systems during transition:
Phase 1 (months 1-3): Build canonical model and ingestion layer. Vendor systems remain authoritative. Your data fabric is read-only, used for analytics and reporting.
Phase 2 (months 4-6): Select one low-risk business process to flip. Customer service ticket queries might read from your database instead of Zendesk's API. Monitor performance and data freshness.
Phase 3 (months 7-12): Incrementally migrate read operations. Your applications query your database first, falling back to vendor APIs only for cache misses.
Phase 4 (months 13-18): Implement write-through to vendors. New records created in your system sync to SaaS platforms for teams still using their interfaces.
Phase 5 (months 19-24): Make your data fabric authoritative. Vendor platforms become optional UI layers that sync from your source of truth.
This timeline assumes a mid-size enterprise with 5-7 core SaaS platforms. Your pace depends on engineering capacity and data complexity.
The key milestone is when you can answer any business question by querying your own database without touching vendor APIs. That's when you've achieved operational sovereignty.
The cost-benefit calculation ctos need
This architecture requires upfront investment. Budget for:
- Engineering time: 2-3 senior engineers for 18-24 months
- Infrastructure costs: $50k-$200k annually depending on data volume
- Migration tools and contractors: $100k-$300k for acceleration
Total investment: $800k-$1.5M over two years for a mid-size enterprise.
The return:
- Eliminated vendor egress fees: $100k-$500k annually depending on current data movement
- Reduced integration maintenance: 30-40% decrease in API connector debugging and updates
- Faster feature development: 2-3x speed improvement when data access isn't bottlenecked
- Improved compliance posture: Quantifiable risk reduction worth millions in avoided breaches
- Increased enterprise valuation: Acquirers pay premiums for companies with sovereign data assets
Break-even typically occurs in year three. The strategic optionality is harder to quantify but often more valuable than the direct cost savings.
You gain the ability to adopt new technologies without vendor permission. Your AI initiatives can train on complete datasets instead of API-limited samples. Your analytics run on fresh data instead of day-old warehouse snapshots.
Most critically, you eliminate the compounding IT debt that slows every enterprise eventually. Five years from now, your competitors will be drowning in integration complexity while your team ships features.
The sovereignty decision tree
This architecture isn't right for every organization. You need it if:
- You're paying five-figure monthly bills for data egress or API overages
- Your data science team complains about data access and freshness
- Integration work consumes more than 20% of engineering capacity
- You're in a regulated industry with strict data custody requirements
- You're building proprietary AI that requires complete training datasets
- Your roadmap includes potential acquisitions that need data consolidation
You probably don't need it if:
- You're pre-product-market fit with under 50 customers
- Your entire data footprint fits in a single CRM
- You have no plans for advanced analytics or AI
- Your team lacks senior infrastructure engineering expertise
For organizations in the middle, start small. Pick your highest-value dataset and prove the model. Build the canonical schema for customer data only. Extract from one vendor. Deploy a single-instance database.
Prove you can maintain parity with vendor data for 90 days without issues. Then expand incrementally.
The next decade
The enterprises that thrive in the next ten years will be those that treated data as a core competency rather than a vendor service.
Your competitive advantages increasingly come from proprietary data insights, not differentiated features. Every SaaS tool can be replicated. Your institutional knowledge, captured in years of operational data, cannot.
Data sovereignty isn't a technical project. It's an assertion that your information assets deserve the same architectural rigor as your product code.
The CTOs who understand this are already building. The question is whether you'll lead the shift or spend years catching up.
Want more on
Business Operations?
Add this topic to your Custom Digest. Drop your email to get our deepest insights on this exact topic.
Ready to fast-track your business?
We combine enterprise-level technical strategy with your existing business to solve complex blockers and accelerate your growth. Let's build something remarkable.
Partner With UsUp Next
Continue your journey into Business Operations.

Modernizing marketing director's blueprint for self-service content
How marketing directors build content operations that eliminate engineering dependencies and accelerate campaign delivery by 60%.
Rationalised SaaS stacks as budget optimisation frameworks
How finance teams cut SaaS spending by 15-30% through centralised portfolio management and vendor consolidation.
Eliminate integration spaghetti with canonical RevOps data models
Learn how canonical data models cut integration complexity by 60% and eliminate the technical debt of point-to-point system connections.