Why generic AI systems fail revenue operations data
Why off-the-shelf AI systems fail at RevOps data quality and what custom-trained models deliver instead.
Key Takeaways
- Generic AI models trained on public data cannot understand your unique CRM schema or sales process nuances.
- Custom-trained AI on your proprietary data cuts data cleaning costs by 40% and improves conversion accuracy.
- Automated data pipelines must cleanse and standardise inputs before AI touches them to maintain pipeline hygiene.
- Continuous monitoring and feedback loops prevent model drift and keep RevOps predictions trustworthy over time.
Generic AI models fail revenue operations because they don't understand your data. They misread custom CRM fields, ignore your sales context, and turn pipeline automation into a data quality nightmare. Here's why custom-trained AI systems are the only way to make RevOps automation actually work.
RevOps leaders face a brutal reality: the AI systems you bought to automate lead scoring and forecasting are creating more problems than they solve.
You've invested in AI-powered platforms promising intelligent automation. Instead, you're watching your operations team spend hours correcting miscategorized leads, debugging phantom pipeline changes, and explaining why the "intelligent" forecast is off by 30%.
The culprit isn't AI itself. It's the fundamental mismatch between generic, pre-trained models and your specific enterprise data architecture.
The hidden cost of black-box AI in RevOps
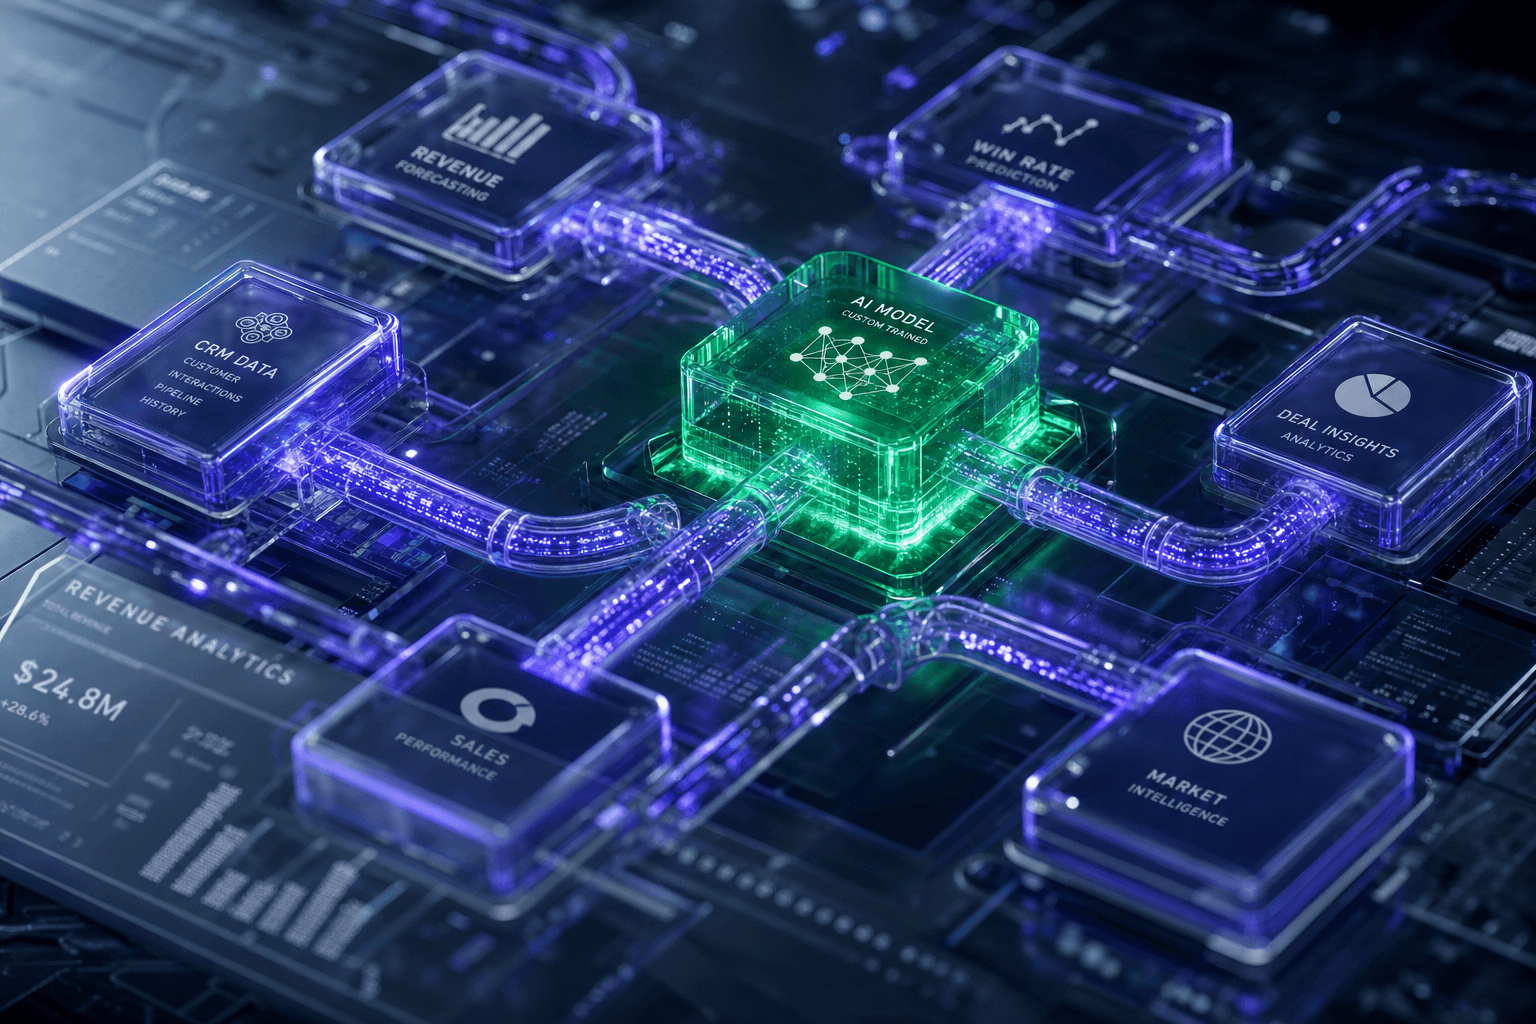
Generic AI models arrive with training data from thousands of companies. They understand common patterns in standard SaaS sales motions. What they don't understand is your business.
Your CRM contains custom fields that track partner influence scores. Your deal stages reflect a technical sales process with proof-of-concept milestones. Your lead sources include proprietary demand generation channels that don't exist in any training dataset.
When you feed this context-rich data into a generic model, it does what it's designed to do: force your unique data into standardized buckets. The model sees your "Technical Champion Identified" stage and treats it like a generic "Qualified" status. It reads your custom industry taxonomy and maps it to broad categories that strip out the nuance your sales team needs.
The result? Lead scores that don't reflect true buying intent. Forecasts that ignore your actual conversion patterns. Pipeline health metrics that trigger false alarms.
Your operations team becomes a permanent cleanup crew, manually overriding AI decisions and maintaining shadow spreadsheets they actually trust.
Why your data architecture determines AI performance
AI accuracy isn't primarily a model problem. It's a data problem.
Generic AI systems expect clean, standardized inputs. They assume consistent naming conventions, predictable data types, and stable schemas. Enterprise RevOps data rarely meets these expectations.
Your HubSpot instance contains:
- 15 custom deal properties created by different teams over three years
- Lead sources with inconsistent naming ("Webinar-Q3" vs "Q3 Webinar" vs "2023_Q3_Webinar")
- Contact records with merged duplicates carrying conflicting field values
- Integration data from six different tools, each with its own data structure
Generic AI can't parse this complexity. It lacks the context to understand that "Enterprise_POC" and "POC - Enterprise" represent the same stage. It can't infer that blank industry fields on contacts created before 2023 should be enriched from account-level data.
Off-the-shelf models treat these inconsistencies as noise. They ignore ambiguous data or, worse, learn incorrect patterns from it. Your AI-powered lead scoring model might learn that blank industry fields correlate with low conversion—not because they do, but because your data hygiene was poor during a specific period.
Building AI systems that understand your revenue engine
The solution isn't abandoning AI. It's engineering systems purpose-built for your data landscape.
This requires three architectural shifts:
Data standardization before model training
Start by auditing every data source that feeds your revenue operations. Map all custom fields, lead sources, deal stages, and contact properties across HubSpot, Salesforce, and any connected systems.
Create a canonical data model—a single source of truth defining:
- Standard field names and allowed values
- Consistent categorization taxonomies
- Data type specifications
- Business rules for data relationships
Implement this model through automated data pipelines that cleanse inputs before they reach your AI. Use n8n or Make to build event-driven workflows that:
- Standardize lead source naming in real-time
- Deduplicate contacts based on email and domain
- Enrich incomplete records from authoritative sources
- Flag anomalies for human review
Your AI models should never see messy data. By the time data reaches the model, it should already conform to your canonical structure.
Custom model training on proprietary data
Generic models optimize for average performance across thousands of use cases. You need models optimized for your specific revenue motion.
Train small, purpose-built models on your cleaned, proprietary dataset. For lead scoring, this means:
- Using your historical conversion data, not industry benchmarks
- Incorporating your custom fields as model features
- Weighting signals based on your actual sales cycle
- Training separate models for different customer segments or product lines
Smaller, focused models trained on high-quality proprietary data consistently outperform large generic models for specific enterprise use cases. A custom lead scoring model with 20 carefully selected features will predict your conversions better than a generic model with 200 features trained on anonymous data.
The same principle applies to churn prediction, deal prioritization, and forecast accuracy. Your proprietary data contains patterns that generic models will never see.
Continuous feedback loops for model refinement
AI models degrade over time as your business changes. New product lines shift your ideal customer profile. Market conditions alter buying behaviors. Your sales process evolves.
Generic AI vendors update models on their schedule, optimizing for their aggregate customer base. Custom systems let you adapt on your timeline.
Build monitoring dashboards that track:
- Model prediction accuracy vs. actual outcomes
- Data drift (changes in input distributions over time)
- Feature importance shifts
- Edge cases where models consistently fail
Create feedback mechanisms that let your RevOps team flag incorrect predictions. When a high-scoring lead doesn't convert, capture why. When a supposedly low-value deal closes for $500K, understand what the model missed.
Use this feedback to retrain models monthly or quarterly. Adjust feature weights based on recent data. Add new features as your data model expands. Remove features that lose predictive power.
This continuous refinement transforms AI from a static tool into a learning system that improves alongside your business.
The operational blueprint for custom RevOps AI
Implementing this approach requires a phased rollout:
Phase 1: Data landscape audit (weeks 1-2)
- Document all data sources feeding RevOps systems
- Map custom fields, stages, and properties across platforms
- Identify data quality issues and inconsistencies
- Define canonical data model for leads, contacts, accounts, and opportunities
Phase 2: Pipeline engineering (weeks 3-6)
- Build automated data cleansing workflows
- Implement real-time deduplication and enrichment
- Create data validation rules and anomaly alerts
- Establish monitoring dashboards for pipeline health
Phase 3: Custom model development (weeks 7-10)
- Select initial use case (typically lead scoring or forecast accuracy)
- Prepare training dataset from cleaned historical data
- Train and validate custom model
- A/B test against existing system or generic model
- Deploy to production with monitoring
Phase 4: Feedback and iteration (ongoing)
- Collect RevOps team feedback on model performance
- Monitor prediction accuracy and data drift
- Retrain models based on new data
- Expand to additional use cases (churn prediction, deal prioritization)
The entire initial implementation typically takes 10-12 weeks. Compare this to the ongoing cost of manual data cleanup and inaccurate predictions from generic systems.
The ROI of purpose-built RevOps AI
Custom AI systems deliver measurable improvements:
Data quality: Automated pipelines eliminate 70-90% of manual data entry and cleanup. Your operations team stops being data janitors and starts being strategic.
Prediction accuracy: Custom models trained on your proprietary data typically improve lead scoring accuracy by 25-40% compared to generic systems. Better scoring means better conversion rates.
Cost reduction: Organizations report 30-50% reductions in time spent on data quality issues, freeing operations resources for higher-value work.
Sales efficiency: Accurate AI predictions help sales teams prioritize the right deals. Companies see 15-25% improvements in lead-to-opportunity conversion rates when reps focus on truly qualified prospects.
Forecast reliability: Custom forecasting models that understand your specific deal patterns and seasonality reduce forecast error by 20-35%, giving leadership confidence in pipeline projections.
The financial impact compounds over time. Better data quality improves every downstream process. More accurate predictions drive better resource allocation. Trusted automation scales without adding headcount.
Moving from generic AI to strategic advantage
Generic AI platforms work well for companies with standard processes and clean data. If your RevOps look like every other company's, off-the-shelf solutions might suffice.
But competitive advantage comes from doing things differently—and better—than your competitors. Your unique sales motion, customer segments, and data architecture should drive better decisions, not get flattened into generic categories.
Custom AI systems turn your proprietary data and processes into a strategic asset. Your competitors using generic AI are optimizing for average performance. You're optimizing for your specific market position.
The technical investment is straightforward: clean data pipelines, purpose-built models, and continuous refinement. The strategic payoff is a revenue engine that gets smarter over time, compounds your competitive advantages, and scales without sacrificing accuracy.
Your RevOps data isn't generic. Your AI shouldn't be either.
Want more on
AI Engineering?
Add this topic to your Custom Digest. Drop your email to get our deepest insights on this exact topic.
Ready to fast-track your business?
We combine enterprise-level technical strategy with your existing business to solve complex blockers and accelerate your growth. Let's build something remarkable.
Partner With UsUp Next
Continue your journey into AI Engineering.
Where LLM hallucinations indicate architectural debt
LLM hallucinations reveal system-level architectural flaws that block enterprise AI adoption and waste engineering resources.
Engineer AI for marketing campaigns on your terms
Build composable AI systems that let marketing teams deploy models and launch campaigns without waiting on engineering.
Continuous AI cost governance as an operational safeguard
How to cut phantom AI costs through active resource governance and automated cost allocation across your entire AI estate.