Untitled
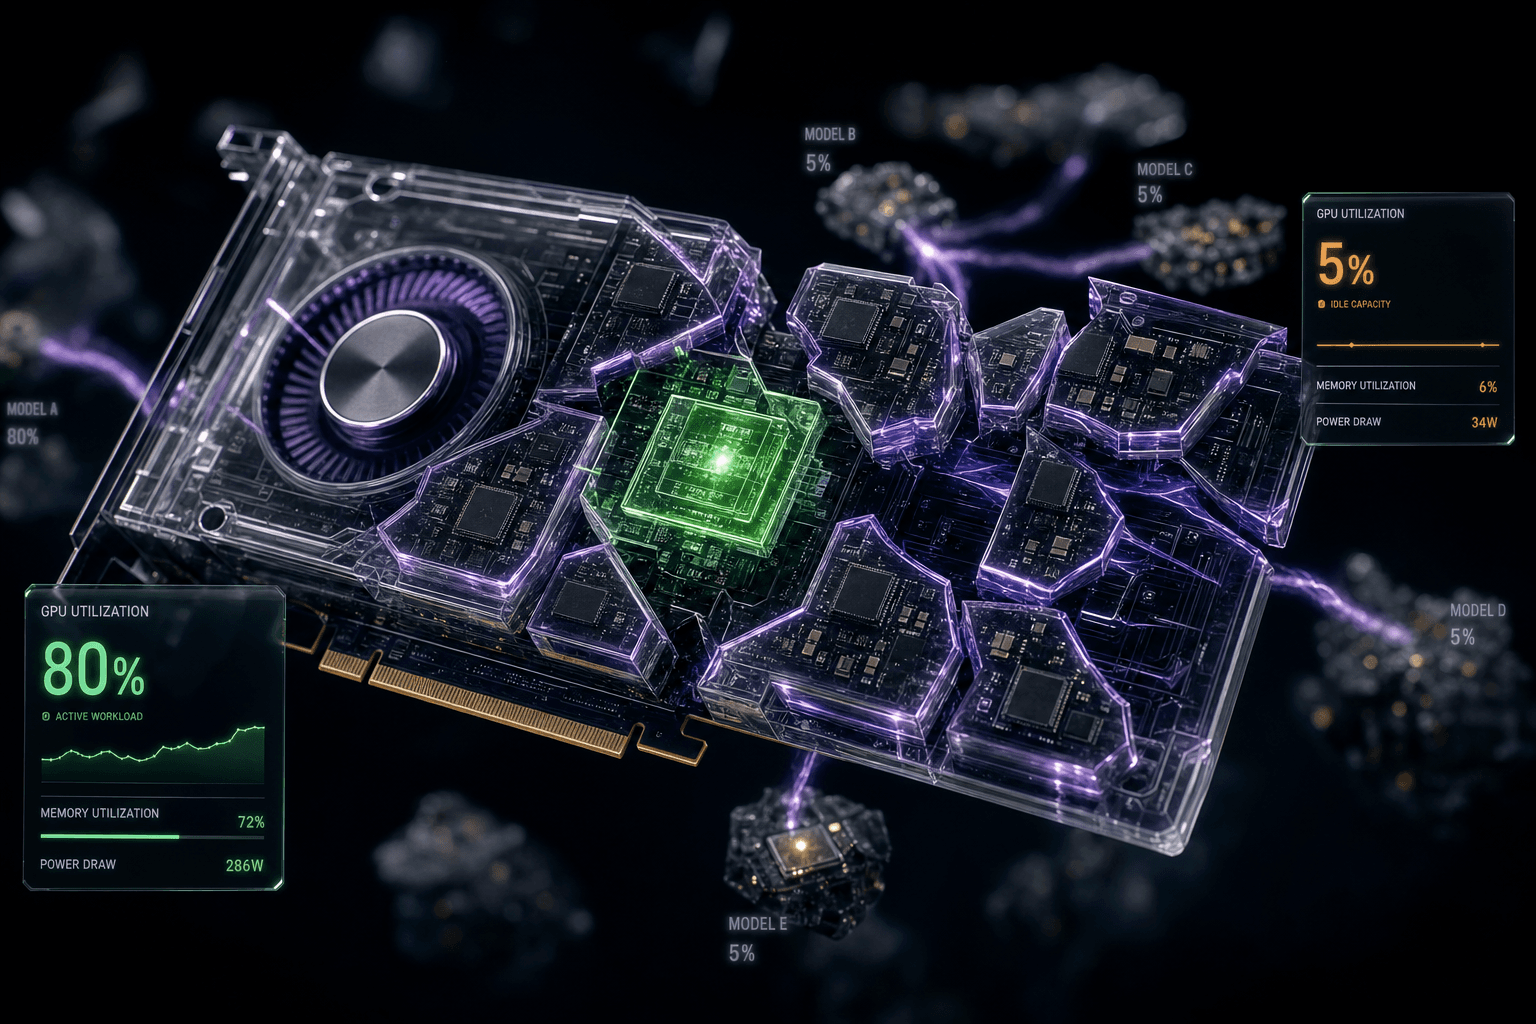
Enterprise GPUs run at 5% utilization on inference workloads while burning 80% of AI budgets—here's how to fix it.
Key Takeaways
- Enterprise GPUs run at 5% utilisation on inference workloads while consuming 80% of AI budgets.
- Continuous batching multiplies throughput 4-8x on the same hardware without changing model quality or architecture.
- Autoscaling to zero during off-peak hours cuts stranded capacity costs in half for bursty traffic patterns.
- Treating tokens as a metered resource inverts system design from latency-first to cost-per-token economics.
Enterprise GPUs are running at 5% utilisation on inference workloads while consuming 80% of total GPU budgets. This isn't a hardware shortage—it's a systems architecture problem. Teams that fix utilisation through continuous batching, autoscaling, and right-sized model assignments are cutting inference costs in half without touching model quality.
Google Cloud's State of Infrastructure report (October 2026) found 83% of organizations say their infrastructure requires upgrades to support agentic AI. But here's the number that matters: Enterprise GPUs run near 5% utilization on inference workloads, while inference consumes up to 80% of total GPU spend.
This is not a scarcity crisis. It's a utilization crisis.
H100 inference running on consolidated training hardware costs enterprises $12.29 per GPU per hour while delivering 5% of capacity value. The math is brutal: a single unoptimized 70B model running 24/7 on an H100 costs ~$90K per month in wasted capacity.
The structural shift nobody saw coming
For five years, enterprise teams provisioned GPU inference capacity like they provisioned traditional compute—buy for peak, leave it idle at trough, and call it a platform cost. That economics has inverted.
Inference economics shifted in Q3 2026 when Blackwell pricing stratification widened the per-hour premium for running inference on training-optimized hardware. Enterprises that consolidated during GPU scarcity (2024-2025) suddenly saw stranded capacity spend as a concrete line item.
Meanwhile, agentic AI adoption is accelerating. Agents issue thousands of queries per minute, which means inference is becoming the dominant workload, not training. Teams sized infrastructure for training-era static workloads are now drowning in inference costs.
The problem: Most enterprise inference architectures were built when tokens felt free (reserved GPU capacity, cost already sunk). Now inference is metered by usage, which inverts the system design constraints. Static provisioning for peak leaves 95% idle capacity at trough. One-request-per-forward-pass means GPUs sit at 5% utilization even when traffic is live.
The companies winning in 2026 are not buying more hardware. They're extracting 3-4x more value per GPU-hour through utilization optimization. The fix is systems-level: continuous batching, autoscaling to zero, and fractional GPU assignment. Teams implementing these practices halve their inference bill without touching model quality.
Three concepts your team needs to understand
GPU utilization vs. workload type mismatch
Training workloads hold 80GB+ in memory continuously, need tight interconnect, and achieve 90-100% utilization when running.
Inference workloads don't need high-memory cards, scale horizontally (many small instances) not vertically, and average 5% utilization when provisioned for peak.
The consequence: Running inference on training hardware (H100, H200) is like renting a container ship to deliver a pizza. Technically possible. Economically absurd.
The continuous batching multiplier
Traditional approach: One request → forward pass → response → GPU idles until next request (5% utilization).
Continuous batching: 100 requests → single batched forward pass → 100 responses (GPU stays busy; 80%+ utilization).
Tools like vLLM implement this at the serving layer. No model changes needed. Same model, same quality, 4-8x throughput on same GPU.
Autoscaling inference (scale-to-zero)
Inference traffic is bursty: peak at 3pm, near-zero at 11pm.
Traditional model: Provision for peak. Waste 95% capacity at trough.
New model: Hold reserved capacity for baseline. Scale elastic capacity up for spikes. Scale down to zero when model unused.
KEDA (Kubernetes Event-Driven Autoscaling) and Ray Serve enable this. Same architecture, continuous cost reduction as utilization rises.
Who this applies to (and who it doesn't)
This matters if you are:
- B2B SaaS companies with inference-heavy workloads (NLP, recommendation engines, generative features)
- Enterprise IT teams running agentic AI pilots and scaling to production
- Companies paying $50K+ monthly on GPU inference with cost sensitivity rising fast
- Teams with models running 24/7 but traffic bursty or episodic
This doesn't apply if you are:
- Running batch processing workloads (training, weekly batch inference)—these already have separate economics
- Processing single-request-per-minute workloads (utilization optimization overhead exceeds benefit)
- On fixed GPU contracts where per-unit cost is already sunk (optimization saves nothing until contract renewal)
The six-phase implementation blueprint
Phase 1: Audit current inference fleet (Week 1-2)
- Pull GPU utilization logs from last 90 days (Prometheus, NVIDIA DCGM, cloud provider dashboards)
- Filter for inference workloads only (exclude training, preprocessing)
- Calculate average utilization during live traffic hours and during idle hours
- Quantify stranded spend: (Average idle utilization % × GPU hourly cost × hours) = monthly waste
- Example: 5% utilization on 10 × H100s @ $12.29/hour = ~$43K/month stranded
Phase 2: Implement continuous batching (Week 3-4)
Audit serving architecture: Is each request being processed independently, or are multiple requests batched?
# Check request arrival rate and forward pass frequency
# If forward passes >> request arrival rate, you have a batching problem
Deploy vLLM as serving layer (if using open-source models):
from vllm import LLM, SamplingParams

llm = LLM(
    model="meta-llama/Llama-3-70B",
    tensor_parallel_size=2,  # Shard across 2 GPUs if needed
    max_model_len=4096,  # Limit context for cost control
    enable_prefix_caching=True,  # Reuse KV cache for common prompts
)

# vLLM automatically batches requests in-flight
# Throughput multiplies 4-8x without model changes
Measure throughput lift: Compare tokens/sec before and after vLLM deployment.
Rollout incrementally: Start with non-critical models. Measure before scaling.
Phase 3: Implement autoscaling + scale-to-zero (Week 5-6)
Baseline measurement: Chart inference traffic by hour for 2 weeks. Identify peak, trough, and idle periods.
Set reserved capacity: Provision GPUs for 30% of peak traffic 24/7 (reserved instances, cheapest tier).
Configure KEDA for elastic scaling:
apiVersion: keda.sh/v1alpha1
kind: ScaledObject
metadata:
  name: inference-autoscale
spec:
  scaleTargetRef:
    name: inference-deployment
  minReplicaCount: 2  # Baseline reserved
  maxReplicaCount: 20  # Elastic ceiling
  triggers:
  - type: kubernetes-workload
    metadata:
      desiredAverageValue: "1000m"  # CPU threshold
      type: Utilization
# For Spot instances (cheaper, preemptible)
# Deploy tolerance-aware workloads (non-critical inference, eval batches)
Monitor scale-to-zero events: Track when inference workloads scale down. Correlate with cost reduction.
Phase 4: Right-size model assignments (Week 7-8)
Audit model-to-GPU mapping: Is a 3B parameter model pinned to a full 80GB GPU?
Enable MIG (Multi-Instance GPU) Partitioning for smaller models:
# NVIDIA MIG: Partition H100 into smaller slices for small models
nvidia-smi -mig 1  # Enable MIG mode
nvidia-smi mig -cgi 9,14,14 -C  # Create GPU instances: 1×7g, 2×1g
Pack multiple small models onto shared GPU slices instead of whole GPU assignment.
Cost impact: 3B model now costs ~$0.30/hour (MIG slice) instead of $12.29/hour (full GPU).
Phase 5: Disaggregate prefill and decode (Optional, high ROI)
Audit workload split: What % of GPU time is spent in prefill (processing prompt) vs. decode (generating output)?
Separate pools for prefill and decode if split is uneven:
- Prefill phase: Compute-bound, needs high-throughput GPUs, short-lived
- Decode phase: Memory-bound, needs memory bandwidth, long-lived (token generation)
Deploy two independent autoscaling pools that each stay busy.
Example: Decode pool idles while prefill queue grows. Autoscale prefill up, decode down independently.
Phase 6: Establish token budget governance (Ongoing)
Treat tokens as a metered resource, not a sunk cost.
Define cost per 1M tokens as a business metric:
Cost/1M tokens = (total GPU spend) / (total tokens generated monthly)

Track and trend weekly. If rising, investigate:
- Are we running unnecessary agents (each call costs tokens)?
- Are prompts growing in size?
- Are models poorly right-sized for the task?
Set token budgets per feature/agent/model and enforce in code:
@token_limit(max_tokens=1000)  # Fail if exceeds 1K tokens
def inference_handler(prompt):
    # Implementation
The mindset shift that matters
This is not about squeezing hardware harder. It's about aligning system architecture to the underlying economics.
When inference was a sunk cost on reserved capacity, latency and throughput drove design. Now that inference is metered, utilization and cost-per-token drive architecture.
Teams that internalize this shift—treating tokens like cloud credits, autoscaling like network load balancing, and continuous batching like connection pooling—will cut infrastructure costs in half without touching model quality. Teams that keep buying more GPUs will scale the waste linearly.
The structural advantage goes to whoever inverts their thinking first. This mirrors the shift from dedicated servers to cloud autoscaling fifteen years ago. The architecture changes before the cost visibility catches up.
Download the GPU Inference Cost Audit Checklist — A step-by-step worksheet (PDF + spreadsheet template) to audit current GPU utilization on your inference fleet, calculate stranded capacity spend, estimate ROI for batching optimization, and plan phase-by-phase rollout (vLLM → autoscaling → MIG → disaggregation).
WrightyMedia Service Offering: "Inference Economics Audit + Implementation Roadmap" — We conduct a 2-week sprint analyzing your inference workloads, quantifying utilization waste, and delivering a prioritized implementation plan with cost projections and technical blueprints.
Sources:
Want more on
Enterprise Architecture?
Add this topic to your Custom Digest. Drop your email to get our deepest insights on this exact topic.
Ready to fast-track your business?
We combine enterprise-level technical strategy with your existing business to solve complex blockers and accelerate your growth. Let's build something remarkable.
Partner With UsUp Next
Continue your journey into Enterprise Architecture.
Why embedded integration is becoming the revenue moat for B2B SaaS
Embedded integrations now separate growing B2B SaaS companies from those losing customers to churn and switching friction.
The governance gap why 40% of enterprise AI agent pilots will be
Why most enterprise AI agent pilots fail governance review and how to architect approval workflows that pass regulatory audit.
How semantic content models automate SEO and content velocity
Learn how semantic content models eliminate engineering dependencies, automate SEO, and accelerate content deployment for enterprise marketing teams.