Why operational risk starts with unverified data integrity
Learn why unverified data integrity creates cascading operational failures and how to architect proactive validation into your enterprise systems.
Key Takeaways
- Unverified data integrity creates operational risk that cripples automation, inflates costs, and erodes trust.
- Embed real-time validation and schema enforcement at every ingestion and transformation point across your stack.
- Treat data quality as code with federated validation services and automated profiling within your pipelines.
- Immutable records and lineage tracking reduce reconciliation overhead and restore confidence in enterprise decision-making.
Unverified data doesn't just create reporting errors. It triggers cascading operational failures: broken automations, bloated cloud costs, and AI models that produce garbage outputs. For CTOs, this means data integrity isn't a quality issue—it's the foundation of operational risk management.
Enterprise systems fail silently. A RevOps automation fires with stale customer data. An AI model trains on inconsistent product attributes. A financial forecast references conflicting revenue figures across three different systems.
The root cause? Unverified data integrity.
CTOs spend millions on cloud infrastructure, machine learning platforms, and automation frameworks. But when the underlying data is inconsistent, every downstream system inherits that operational risk. Manual reconciliations become the norm. Engineers waste cycles debugging phantom issues. Business leaders lose confidence in dashboards.
This isn't a data science problem. It's an architectural one.
The hidden cost of data inconsistency
Flawed data creates a cascade of operational failures:
- RevOps automations break: Lead routing rules fire incorrectly when contact records contain duplicate or outdated information
- AI models produce garbage: Machine learning accuracy degrades when training data lacks semantic consistency
- Cloud costs spike: Reprocessing failed jobs and running reconciliation pipelines inflates compute expenditure
- Trust erodes: Finance teams question sales reports when numbers don't match across systems
- Engineering velocity drops: Developers spend more time investigating data anomalies than shipping features
Data debt compounds faster than technical debt. A single unchecked schema drift can corrupt months of analytics. One missing validation rule can trigger thousands of failed workflows.
Most enterprises treat data quality as a periodic cleanup task. They run batch validation jobs weekly or monthly. They hire data stewards to manually inspect records. They build reconciliation scripts that patch symptoms without addressing root causes.
This reactive approach guarantees failure at scale.
From reactive cleansing to proactive integrity
The strategic shift required is architectural: embed data integrity as a first-class concern throughout the entire data lifecycle.
Stop thinking about data quality as a separate initiative. Start treating it as a code concern that lives in your deployment pipelines, API contracts, and event streams.
This means moving from:
- Periodic batch validation → Real-time validation at ingestion
- Manual data stewardship → Automated profiling and anomaly detection
- Siloed quality checks → Federated governance with decentralised enforcement
- Hope-based consistency → Schema contracts and semantic verification
The goal isn't perfect data. It's predictable, verifiable data that maintains integrity at every transformation point.
When data enters your system, it should be validated immediately. When it moves between services, those transfers should enforce contracts. When it reaches consumption points, lineage should be traceable.
This architectural pivot requires three foundational shifts.
Three pillars of architected data integrity
Federated validation at ingestion points
Don't let bad data enter your systems in the first place.
Architect microservices or serverless functions that validate data against business rules and schemas at the point of origin. Deploy these validation services directly into:
- API gateways that process external integrations
- Event streams that handle real-time data flows
- ETL pipelines that ingest batch data
- Form submission endpoints that capture user input
Each validation service should enforce:
Schema compliance: Data types, required fields, format constraints Business rules: Valid ranges, referential integrity, cross-field dependencies Semantic consistency: Standardized enumerations, canonical representations, controlled vocabularies
When validation fails, reject the data immediately. Don't store corrupted records and hope to clean them later. Surface errors to upstream systems with clear, actionable feedback.
This approach shifts the burden of data quality upstream to the producers. They fix issues at the source rather than forcing downstream consumers to work around inconsistencies.
Semantic catalogues with continuous profiling
You can't manage what you can't measure.
Deploy a metadata management platform that does more than list tables and columns. It should:
- Continuously profile data quality metrics (completeness, uniqueness, distribution)
- Flag statistical anomalies and schema drift automatically
- Document semantic meaning and business context for each data asset
- Track which teams own which datasets and who consumes them
Link this catalogue to a data contract framework. Every data producer should publish a versioned contract that specifies:
- Expected schema and data types
- Quality thresholds and service level objectives
- Update frequency and latency guarantees
- Breaking change policies and migration paths
Consumers can then code against these contracts with confidence. When producers change their schema, contracts break explicitly rather than silently corrupting downstream pipelines.
This creates accountability. Producers can't ship breaking changes without warning. Consumers can't blame mysterious data issues on unknown upstream systems.
Immutable records with full lineage
When data integrity breaks, you need to trace the failure back to its source quickly.
Implement data warehousing or lakehouse patterns that support immutable records. Instead of updating data in place, append new versions with timestamps. This creates a complete audit trail of every change.
Pair immutability with robust lineage tracking. Use metadata solutions that capture:
- Source system and ingestion timestamp
- Transformations applied at each processing stage
- Dependencies between datasets and derived tables
- Consumption points and downstream impacts
When an integrity issue surfaces, lineage lets you:
- Identify which upstream system introduced the error
- Determine which downstream reports or models are affected
- Replay transformations with corrected data
- Calculate the blast radius of the incident
This visibility transforms incident response from guesswork into forensic analysis. You move from "the data is wrong somewhere" to "this specific transformation failed at this timestamp for these records."
Implementation priorities
Start with the highest-risk data flows. Identify which datasets:
- Feed critical RevOps automations that affect revenue
- Train production AI models that inform business decisions
- Support regulatory reporting with compliance requirements
- Serve external customers through APIs or dashboards
Implement validation, cataloguing, and lineage for these flows first. Prove the value with measurable outcomes:
- Reduced time spent on manual reconciliation
- Fewer failed automation runs and support tickets
- Improved accuracy of forecasts and reports
- Faster root cause analysis for data incidents
Then expand systematically. Build validation services as reusable libraries. Codify business rules in version-controlled repositories. Train teams to think about data contracts as API contracts.
Treat data integrity as a continuous architectural practice, not a one-time project.
The business case for data integrity
This isn't theoretical. Poor data quality costs enterprises millions:
- Engineering teams spend 30-40% of their time debugging data issues
- Failed automations require manual intervention that doesn't scale
- Inaccurate reports lead to bad strategic decisions
- Cloud reprocessing costs compound monthly
- Technical debt from workarounds slows future development
Architected data integrity delivers measurable returns:
Reduced operational expenditure: Eliminate manual reconciliation and error debugging Improved automation reliability: RevOps workflows execute correctly without human intervention Accurate AI insights: Models trained on clean data produce trustworthy predictions Faster engineering velocity: Developers ship features instead of investigating data anomalies Built trust: Business leaders make confident decisions based on verified metrics
The ROI compounds over time. Every data flow you fix reduces the surface area for future failures. Every validation rule you codify prevents an entire class of errors. Every lineage path you document accelerates the next incident response.
Data integrity isn't a cost center. It's operational leverage.
Risk mitigation at scale
Enterprise data systems grow more complex every quarter. New integrations add dependencies. New teams introduce inconsistent practices. New regulations demand stricter controls.
Without architected integrity, this complexity creates exponential risk. One broken integration can cascade through dozens of downstream systems. One unchecked schema change can invalidate months of analytics.
Proactive data integrity turns complexity into a manageable problem:
- Validation services contain failures at ingestion points
- Data contracts make dependencies explicit and testable
- Lineage tracking enables rapid incident response
- Continuous profiling surfaces issues before they cause outages
You shift from fighting fires to preventing them. From reactive debugging to predictive monitoring. From hope to verification.
This architectural foundation supports every other enterprise initiative. Better data enables better automation. Better automation enables better AI. Better AI enables better decisions.
But it all starts with integrity.
Build trust in your data assets
CTOs face a choice: accept data inconsistency as an inevitable operational cost, or architect systems that enforce integrity by design.
The first path leads to escalating technical debt, eroding trust, and diminishing returns on data investments.
The second path requires upfront architectural work but delivers compounding value: reliable automations, accurate insights, reduced costs, and faster engineering velocity.
Enterprise data systems should be verifiable, not hopeful. Predictable, not mysterious. Trustworthy by architecture, not by accident.
Start with your highest-risk data flows. Implement federated validation. Build semantic catalogues with continuous profiling. Track lineage for every transformation.
Then expand systematically. Codify business rules. Enforce contracts. Treat data integrity as a first-class code concern.
The operational risk you eliminate today prevents the fire drills you'll face tomorrow.
Want more on
Business Operations?
Add this topic to your Custom Digest. Drop your email to get our deepest insights on this exact topic.
Ready to fast-track your business?
We combine enterprise-level technical strategy with your existing business to solve complex blockers and accelerate your growth. Let's build something remarkable.
Partner With UsUp Next
Continue your journey into Business Operations.
Reducing integration debt opex with event-driven data fabrics
How event-driven integration cuts operational costs by eliminating technical debt and reducing manual IT overhead.
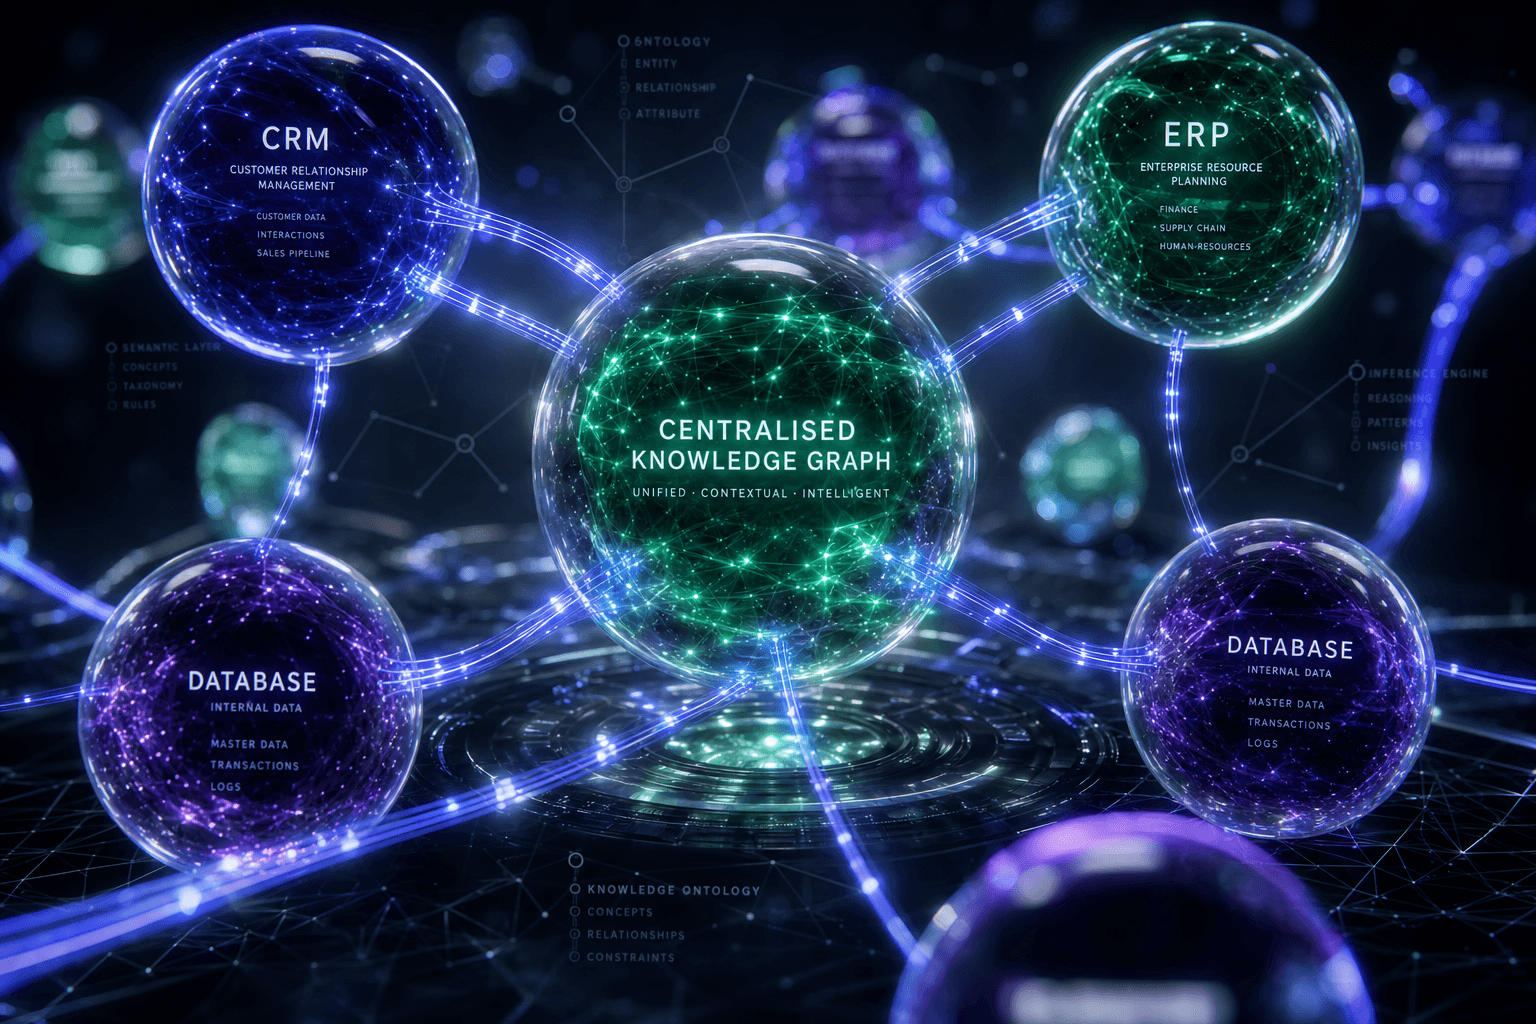
Dismantling enterprise data silos with centralised knowledge graphs
How a unified knowledge graph cuts IT integration costs and powers real-time decisions across fragmented enterprise systems.
Eliminating SaaS wastage through continuous licence optimisation
A practical framework for finance teams to eliminate unused SaaS licences and cut recurring software costs through continuous monitoring.