Cut growth system vendor lock-in and data debt
How a vendor-agnostic data architecture cuts integration costs, breaks vendor lock-in, and turns growth data into a strategic asset.
Key Takeaways
- Proprietary data structures and brittle ETL pipelines create IT debt that blocks scalable revenue growth.
- A vendor-agnostic data architecture with a canonical model reclaims control and eliminates platform lock-in.
- Centralised data governance through open APIs cuts integration costs and accelerates time-to-market for growth initiatives.
- Owning your growth data foundation reduces licence fees and transforms data from liability into strategic asset.
Your enterprise growth stack is haemorrhaging money through vendor lock-in and brittle integrations. Each CRM, marketing platform, and sales tool creates data debt that compounds monthly, forcing you into expensive ETL tools and vendor-dictated roadmaps. Here's how to break free and turn fragmented growth data into a controlled, cost-efficient asset.
Your enterprise growth stack is bleeding money. Not from the licence fees—those are visible. The real cost is hidden in the brittle ETL pipelines you've built to stitch together CRM, marketing automation, and sales intelligence platforms that were never designed to talk to each other.
Each vendor's proprietary data model creates a new integration tax. Your engineering team spends weeks mapping fields, transforming schemas, and maintaining custom connectors that break with every platform update. This is data debt, and it compounds faster than technical debt because it touches every growth decision your business makes.
For CTOs managing enterprise revenue systems, this isn't just an operations headache. It's a strategic liability that caps your ability to scale, experiment, or exit a failing vendor relationship without triggering a multi-quarter migration project.
The vendor lock-in trap
Most enterprise growth platforms follow a predictable pattern: they make it easy to import data, then create friction at every exit point. The lock-in happens at the schema level.
When your customer records live in Salesforce's object model, your marketing segments in HubSpot's proprietary structure, and your product usage data in Segment's format, you don't own your data in any meaningful sense. You own copies that exist in incompatible formats, each requiring translation layers to communicate.
The symptoms appear gradually:
- Integration projects that were scoped for 2 weeks stretch to 8
- Data quality degrades as transformations multiply
- New tool evaluations get vetoed because "we can't integrate it"
- Analytics teams can't answer basic questions without waiting for data engineering
- Platform migrations become boardroom-level decisions due to technical risk
This fragmentation doesn't just slow you down. It makes your data useless for the predictive analytics and AI applications that could actually move revenue metrics.
The architectural shift required
The solution isn't another integration platform. Adding Zapier, Make, or Workato on top of your existing chaos just creates another dependency and another transformation layer.
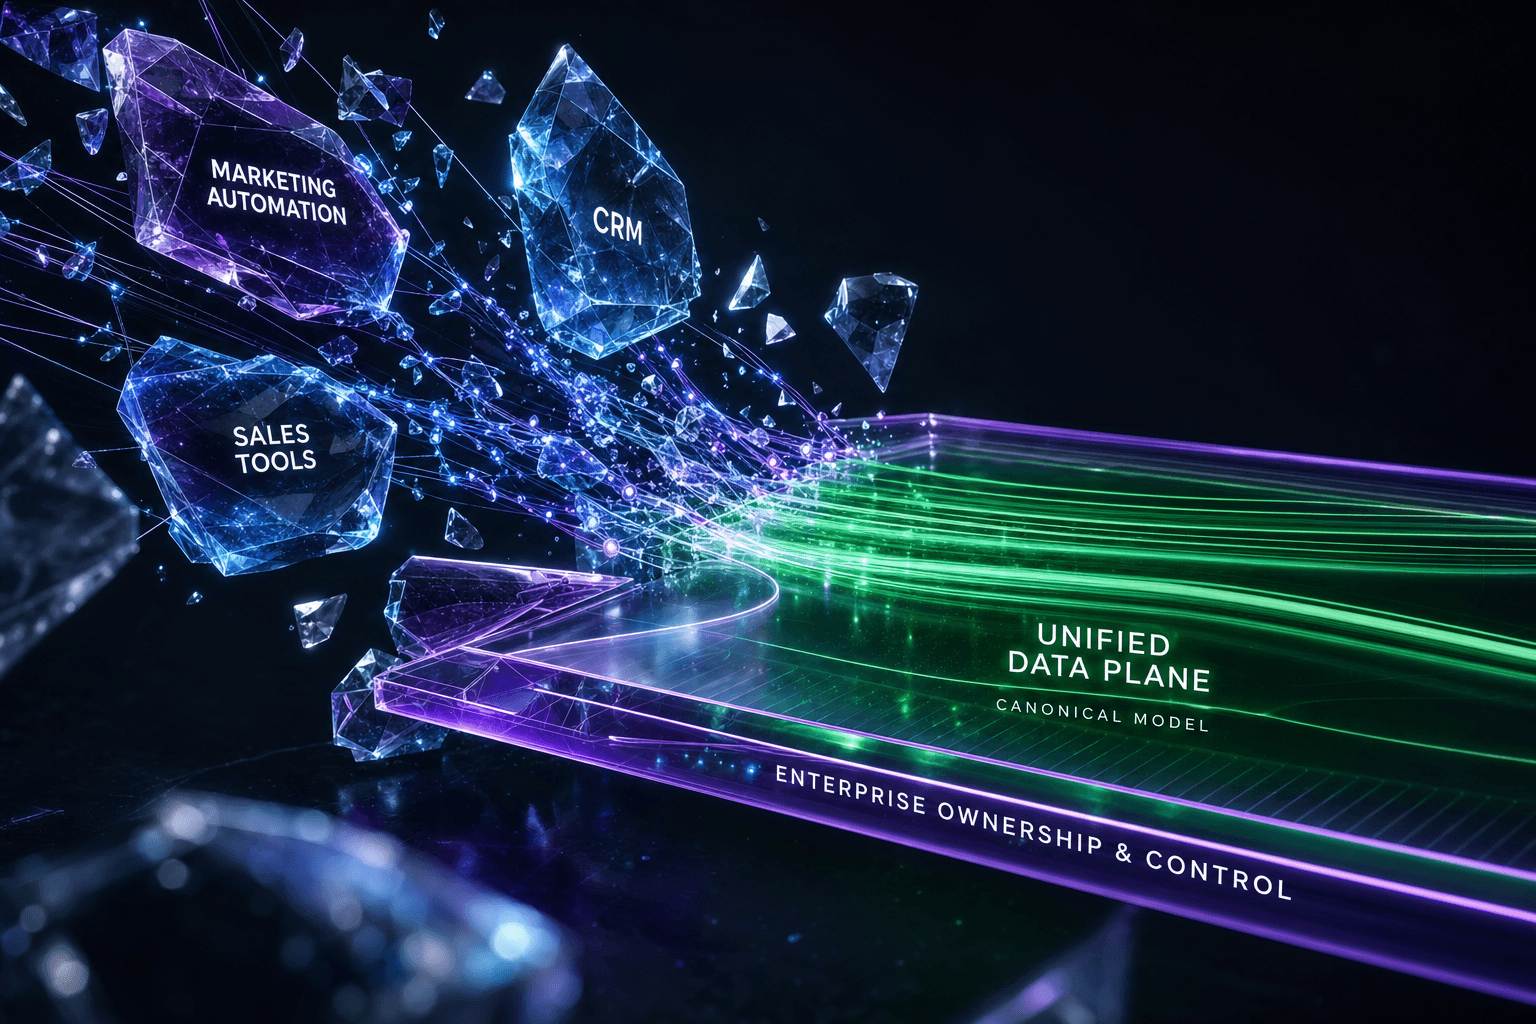
What your enterprise needs is a fundamental architectural change: a vendor-agnostic data plane that you own and control.
This means building a canonical data model—a single, normalised schema that defines how your enterprise thinks about customers, opportunities, and revenue. Not Salesforce's definition. Not HubSpot's. Yours.
Every system becomes a satellite. They publish events to your central data plane. They consume data through your APIs. The platforms become interchangeable components rather than foundational architecture.
This shift requires three capabilities your current stack probably doesn't have:
- A unified data model independent of any vendor: Define customer, lead, account, and opportunity entities once, in a format you control
- An event-driven ingestion layer: Capture every state change from source systems without coupling to their schemas
- A governed API layer: Expose harmonised data through standardised endpoints that internal teams and partners can consume
The goal is simple: when you decide to swap out your CRM, marketing automation, or analytics platform, the migration is a weeks-long implementation project, not a year-long replatforming initiative.
Blueprint for execution
This transformation follows a deliberate sequence. Trying to rebuild everything at once creates more risk than the problem you're solving.
Define your canonical model
Start with a cross-functional working group. You need representation from RevOps, sales leadership, marketing operations, and data engineering. The product team should participate if product usage drives your growth motion.
Identify your critical entities. For most B2B enterprises, this includes:
- Person: The individual human, independent of their company affiliation
- Account: The organisation, with hierarchy if you sell to enterprises
- Opportunity: The deal, with stages that map to your actual sales process
- Activity: Interactions that indicate intent or engagement
- Product usage: Behavioural data if you run product-led growth
For each entity, define the authoritative attributes. What fields are required? What's optional? What's calculated? Where does each piece of data originate?
This process surfaces painful truths. You'll discover that "customer" means different things to sales and support. You'll find that three systems track deal value using incompatible logic. Good. Document these conflicts and resolve them now, not during a production incident.
Store this model as code. JSON Schema or Apache Avro schemas work well. Version control is non-negotiable. Every change to the canonical model should go through review, because this becomes your data contract.
Build your ingestion pipeline
Your data plane needs to capture changes from source systems without forcing them to conform to your model immediately. This is critical for minimising disruption and maintaining system independence.
Implement an event-driven architecture:
- Each source system publishes change events (create, update, delete) to a message bus
- Events are captured in their native format first
- A separate transformation layer maps native formats to your canonical model
- Raw events and transformed records both persist in your data lake
Use open formats for storage. Apache Parquet for structured data, Avro for event streams. Store everything in an object storage layer you control—S3, Google Cloud Storage, or Azure Blob Storage.
The key architectural decision: separate ingestion from transformation. Your pipeline should capture raw events even if the transformation logic hasn't been written yet. This means you never lose data during the migration period.
For high-volume sources (web analytics, product telemetry), batch loads are acceptable. For systems of record (CRM, billing), you need near-real-time change data capture. Most modern platforms offer webhook notifications or streaming APIs that make this possible without polling.
Expose data through governed APIs
Your canonical data model only creates value when internal systems can consume it. This requires an API layer that handles authentication, authorisation, rate limiting, and audit logging.
Build a REST or GraphQL API gateway that:
- Exposes canonical entities through standard CRUD operations
- Enforces field-level permissions based on requesting system and user context
- Logs every access for compliance and debugging
- Provides webhook subscriptions so consuming systems get notified of changes
- Versions endpoints to allow backward-compatible schema evolution
This API becomes your internal data product. Marketing automation pulls segment definitions. Analytics tools query for attribution data. Custom applications get customer context without touching the CRM directly.
The governance layer is what prevents this from becoming another integration nightmare. Every API consumer goes through the same controlled interface. You can swap the underlying storage, change transformation logic, or migrate platforms without breaking downstream consumers.
The business case
This architectural shift requires upfront investment. You're building infrastructure that doesn't directly generate revenue. Finance will ask why you're not just buying another integration tool.
The ROI comes from three sources:
Reduced integration maintenance: Point-to-point integrations scale exponentially. With 10 systems, you potentially need 45 integrations. A hub-and-spoke architecture needs 10. Your data engineering team stops being an integration factory and starts building analytics that matter.
Faster time-to-market: When a new growth tool enters the evaluation, the integration question becomes: can it publish events and consume our API? If yes, the technical risk drops to near zero. You can experiment with new platforms in weeks rather than quarters.
Lower platform switching costs: Vendor relationships become negotiable again. When a platform raises prices 40%, degrades service, or simply stops innovating, you can credibly threaten to leave. The data migration that used to take 18 months now takes 6 weeks. This negotiating position saves more than the infrastructure costs.
The strategic value is harder to quantify but more important: you can finally build the predictive models and AI applications that require clean, unified data. Customer lifetime value models that incorporate product usage and support interactions. Churn prediction that sees signals across the entire customer journey. Lead scoring that actually correlates with conversion.
These capabilities don't exist in fragmented data environments. The analysis required to join datasets across platforms takes so long that the insights are obsolete before they reach decision-makers.
Rollout strategy
Don't attempt a big-bang migration. This infrastructure gets built incrementally while existing integrations continue running.
Start with one high-value entity. Customer records are usually the best choice because they flow through every system and cause the most integration pain.
Build the canonical customer model. Implement ingestion from your CRM and one other source. Create the API endpoints for read access. Then migrate one low-risk consumer to pull from your API instead of directly querying the CRM.
Validate data quality obsessively during this pilot. Compare API responses to direct database queries. Run parallel systems until you're confident the transformation logic handles edge cases correctly.
Once the first entity is stable, expand to the next. Opportunity data is usually second because it connects to customer records you've already modelled. Then activities, then product usage.
Each iteration de-risks the next one. Your team builds familiarity with the architecture. Edge cases get documented. The API stabilises.
Plan for 9-18 months to reach full coverage across your growth stack, depending on data volumes and system complexity. This timeline feels slow compared to buying an integration platform, but you're building infrastructure that eliminates classes of problems rather than solving individual integrations.
Common failure modes
This architecture fails when teams treat it as a pure engineering project rather than a cross-functional capability.
The most common mistake: IT builds the canonical model in isolation, then tells business teams to adapt. This produces schemas that are technically elegant but operationally useless. The model needs to reflect how your business actually operates, not how an architect thinks it should operate.
Second failure mode: trying to achieve perfect normalisation before shipping anything. Your canonical model will be wrong in places. That's acceptable if you've versioned it properly and built the transformation layer to be flexible. Ship the 80% solution and refine based on real usage.
Third mistake: underinvesting in data quality monitoring. Raw ingestion captures bad data just as efficiently as good data. You need automated testing that validates schema compliance, checks referential integrity, and flags statistical anomalies. Without this, your clean architecture becomes a high-speed pipeline for garbage.
The path forward
Vendor lock-in isn't a technology problem. It's an architecture problem that compounds over time until the cost of change exceeds the cost of staying locked in.
Breaking free requires treating data as a first-class product that your enterprise owns and controls. Not data warehousing. Not another integration layer. A fundamental shift in how you architect the relationship between growth platforms and the data they generate.
The enterprises that make this shift gain strategic optionality. They can adopt new platforms faster. They can negotiate better terms with existing vendors. They can build competitive advantages from unified data that fragmented competitors can't match.
The alternative is watching your data debt compound until your growth systems become a constraint on growth itself.
Want more on
Growth Systems?
Add this topic to your Custom Digest. Drop your email to get our deepest insights on this exact topic.
Ready to fast-track your business?
We combine enterprise-level technical strategy with your existing business to solve complex blockers and accelerate your growth. Let's build something remarkable.
Partner With UsUp Next
Continue your journey into Growth Systems.
How semantic data pipelines automate enterprise content assembly
Break the developer dependency cycle by automating content assembly with semantic pipelines that cut publishing time by 40%.
Application licence optimisation through unified data orchestration
How unified data orchestration cuts SaaS licence waste and turns your enterprise application stack into a profit centre.
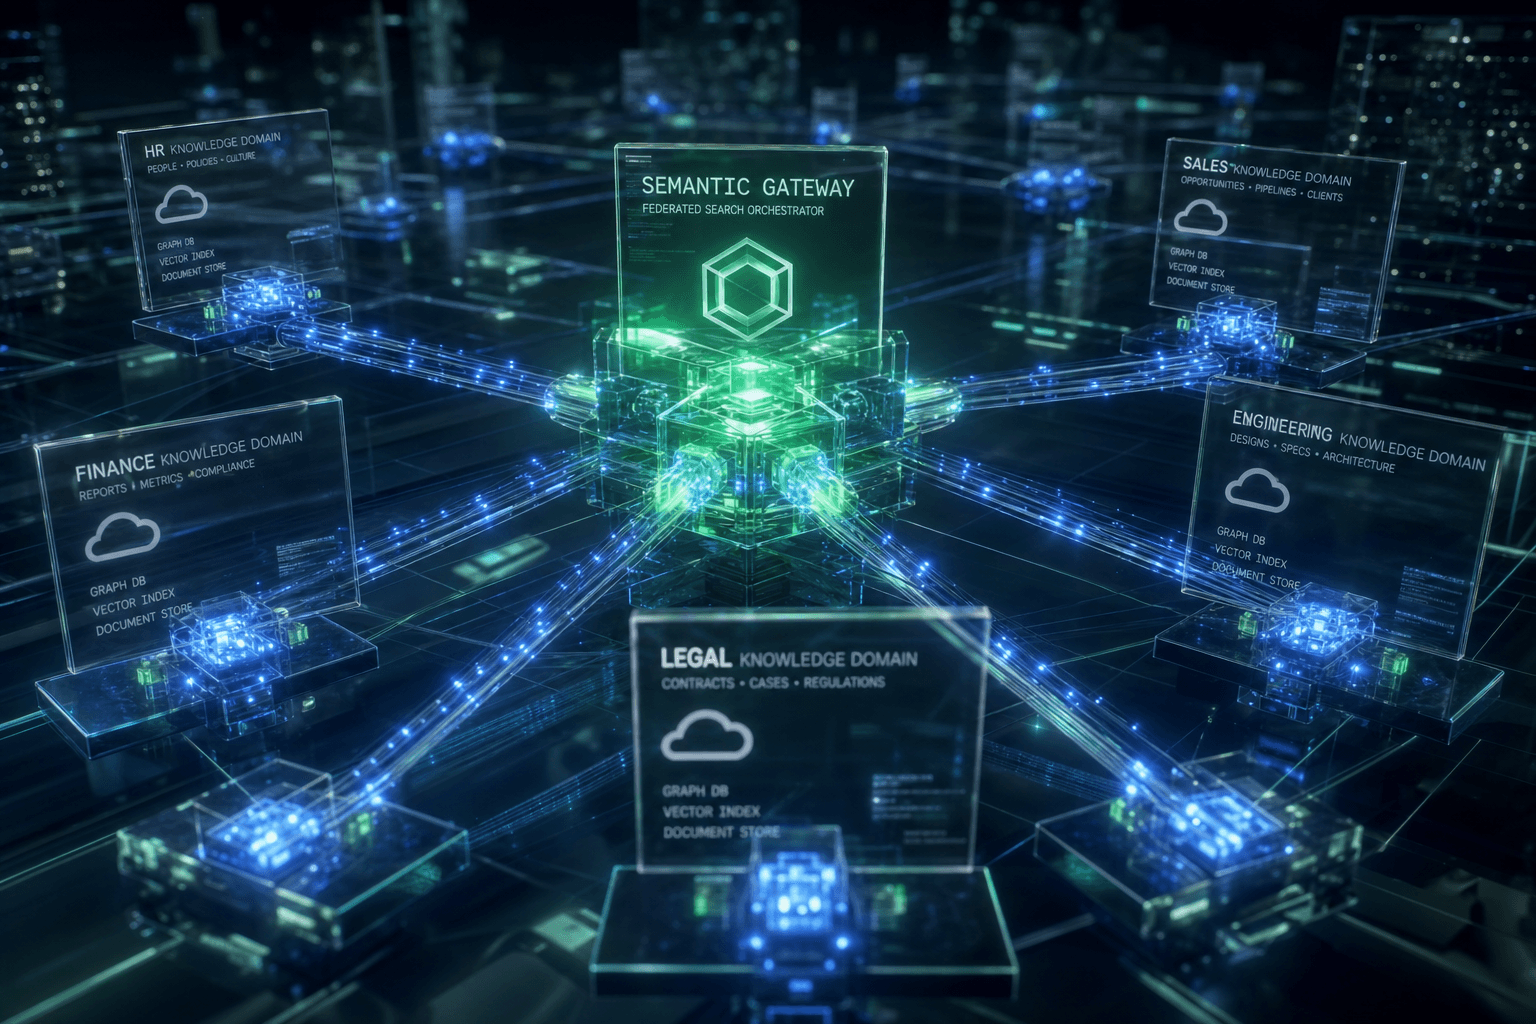
Federated knowledge planes as modern enterprise search layers
CTOs can unify fragmented enterprise data through federated knowledge planes, cutting search time and reducing IT debt.